
LFM3-1.7B vs Qwen3.5-9B: The 1.7B Model Wins on Tool Calls, Then Loses on Reasoning and Long Context
Liquid AI's own table shows LFM3-1.7B ahead on IFEval, BFCL and LiveCodeBench but 17 points behind on GPQA. Ollama 0.40.13 runs it on every desktop.
Research desk
Technical reporting for reverse engineering, cloud security labs, vulnerability analysis, AI tooling, and defensive testing.
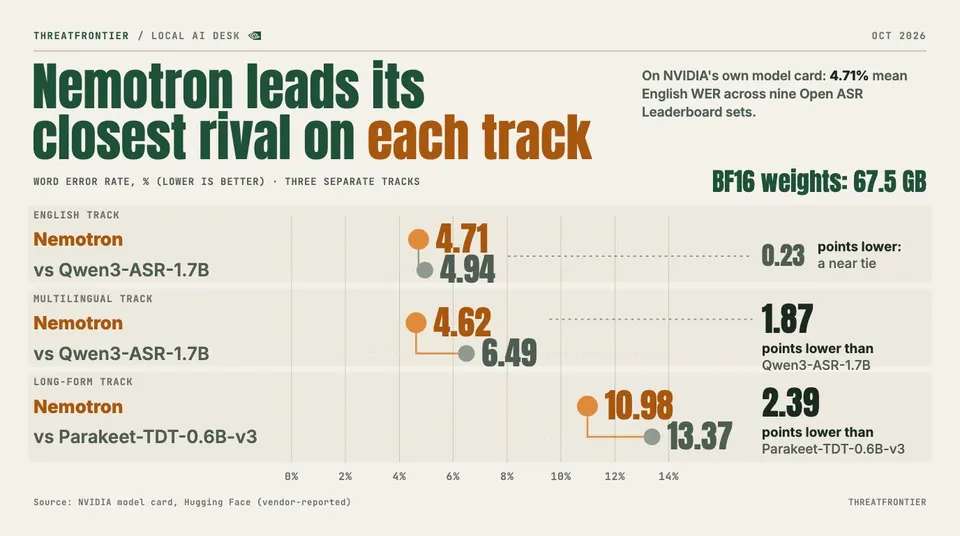
NVIDIA's open-weight speech model beats Qwen3-ASR and Parakeet on its own card, but BF16 weights are 67.5 GB. Which formats fit 16, 24 and 32 GB cards.
Liquid AI's own table shows LFM3-1.7B ahead on IFEval, BFCL and LiveCodeBench but 17 points behind on GPQA. Ollama 0.40.13 runs it on every desktop.

Ollama releases between 24 and 28 October add macOS speech over /v1/audio/speech, d3 decision models, LFM3 on Linux and Windows and DFlash2 drafts on MLX.

Nanbeige's new 33B open model leads Qwen3.8-27B on terminal and agent tasks in vendor-run tests, loses SWE-Bench Pro, and needs care to fit 16-32 GB.

Claude Code now compacts idle 200K-token sessions before the prompt cache expires and warns Pro and Max users before costly resumes. Here is what changed.