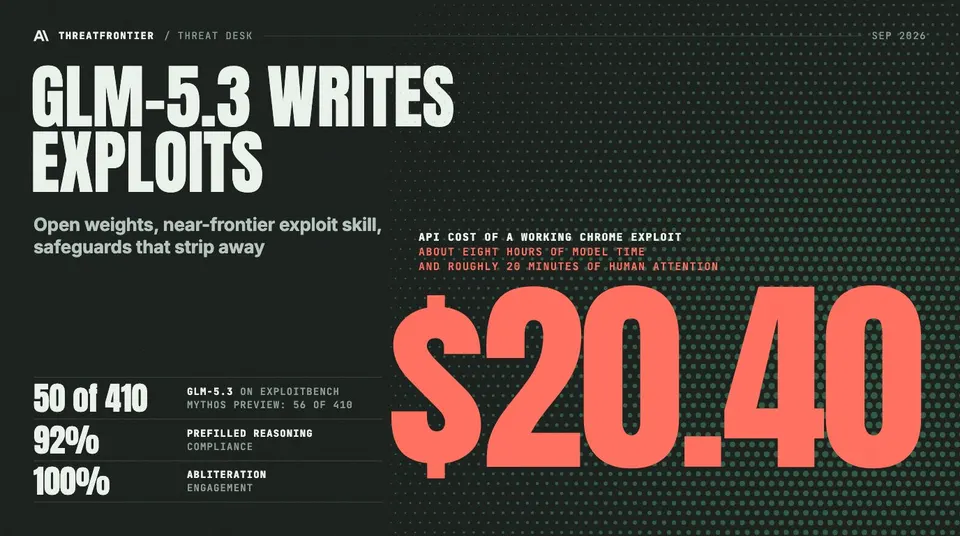
Anthropic finds open-weight GLM-5.3 solves 50 of 410 ExploitBench exploits, near Mythos Preview, and its safeguards fall to abliteration.
Anthropic's Frontier Red Team says Z.ai's open-weight GLM-5.3 is the first publicly downloadable model to come close to Claude Mythos Preview at writing working exploits. On ExploitBench, GLM-5.3 completed 50 of 410 end-to-end exploits (12%), against 56 of 410 (14%) for Mythos Preview. Claude Opus 4.6, GLM-5.2, Kimi K3 and DeepSeek V4.1-Flash scored at or near zero. Anyone who can download the weights can now run this capability without a vendor in the loop.
What Anthropic measured
The analysis, published 29 September 2026 by Andrew Fasano, Marius Fleischer, Cole McFaul, Robert Xiao and Tripp Gallagher, uses ExploitBench, which measures how well models can exploit vulnerabilities in Chrome's V8 engine. On a separate binary-exploitation benchmark, GLM-5.3 achieved control-flow hijacks 4% of the time versus 6% for Mythos Preview; earlier models managed 0%.
In a case study, the team used GLM-5.3 through Zhipu's API to build a Chrome exploit for an ARM64 target, including a bypass of pointer authentication (PAC) hardening. The run cost $20.40 in API compute, took about eight hours of model time and roughly 20 minutes of human attention. It relied on CVE-2026-11645, a V8 out-of-bounds memory access bug that Google fixed in Chrome 149.0.7827.102/.103 on 8 June 2026 after reports of in-the-wild exploitation. Anthropic's page describes it alongside another known flaw; the second bug was not confirmed in the sources read.
Safeguards do not hold
GLM-5.3 ships with some built-in safeguards. Anthropic tested three ways around them:
- Deceptive prompts. False red-team cover stories drew engagement 64% of the time (50 samples per cell).
- Prefilled reasoning. Pre-populating the thinking tokens so the model appears already committed produced 92% compliance.
- Abliteration. Removing the refusal direction from the weights gave 100% engagement. Refusals fell from 95% to about 6%. A team with no prior experience needed about 2,200 GPU hours (about $4,400), with minimal capability loss.
Because the weights are public, the third route cannot be recalled or patched by the vendor.
Independent corroboration
NIST's Center for AI Standards and Innovation (CAISI) published its own assessment on 17 September 2026. It calls GLM-5.3, released by Z.ai on 14 August with weights following about two weeks later, "the most cyber-capable open-weight model released to date", yet roughly four months behind the US frontier. CAISI's scores: SEC-Bench Pro 40.4% (frontier best 90.2%), ExploitBench 61.1% (100%), ExploitGym 9.4% (44.4%), OSS-Fuzz 7.7% (23.2%). CAISI's ExploitBench percentages are on a different scale from Anthropic's 50-of-410 count, so they should not be compared directly.
What defenders should do
- Treat browser exploit development as cheap. Patch Chrome and Chromium-based browsers promptly; anything at or above 149.0.7827.102 includes the CVE-2026-11645 fix.
- Shorten the window between patch release and exploitation. Models of this class can work from known bug details in hours, for tens of dollars.
- Do not rely on model refusals in open-weight systems as a control in threat models.
- Expect pressure for government safety testing of capable open-weight successors, which Anthropic explicitly recommends.