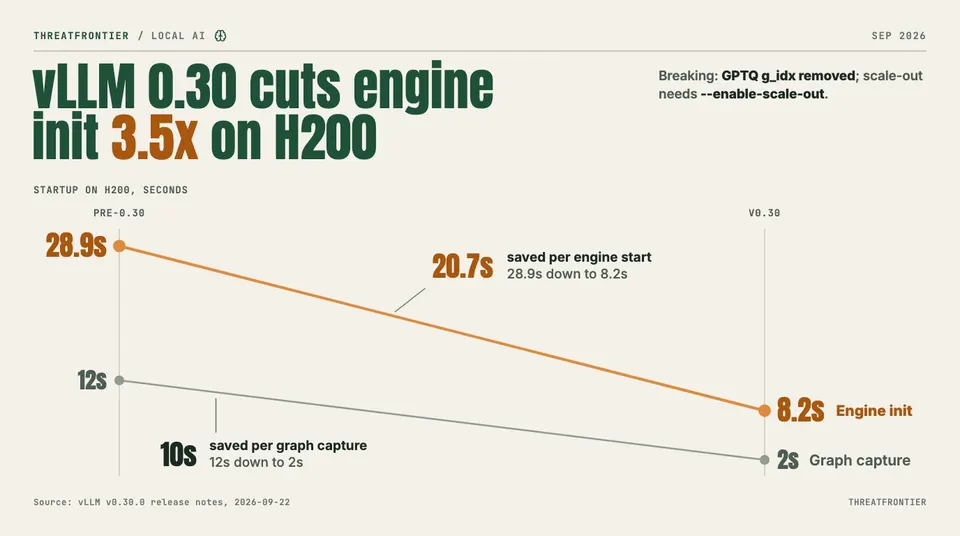
vLLM v0.30.0 adds DeepSeek-V4.1-Flash, GLM-5.3-Flash, Fast Start and HiSparse, and changes defaults that can break an upgrade. What to check.
vLLM v0.30.0 shipped on 2026-09-22 with 762 commits from 315 contributors, 104 of them new. It adds support for DeepSeek-V4.1-Flash and GLM-5.3-Flash, a weight-cache daemon called Fast Start, a host-memory tier for sparse-MLA decode called HiSparse, and a set of quantization additions. It also removes or changes several defaults. Anyone running vLLM behind a gateway, on GPTQ checkpoints, or on long-context YaRN models should read the breaking-change list before bumping.
As of 2026-10-03 there is no v0.30.x patch release on the project's releases page. The repository carries a v0.30.1rc0 tag from 2026-09-23 and v0.31.0rc4 from 2026-10-02, so v0.30.0 is the current stable build.
What is new
Fast Start. A persistent per-GPU daemon holds post-quantized, tensor-parallel-sharded weights in GPU memory. Restarting engines map them over CUDA IPC with --load-format ipc_cache instead of reloading from disk. The release extends it to FP4 checkpoints and multi-node TP, and adds per-client IPC tensor export so a copy-mode client cannot release weights another client maps zero-copy.
The 28.9s to 8.2s figure. The notes report engine init dropping from 28.9s to 8.2s on H200, and CUDA graph capture from 12s to 2s. Per the notes, that comes from freezing garbage collection during graph capture (#54646), listed under Model Runner V2. It is a separate change from the Fast Start daemon, so do not expect the daemon to account for those numbers.
HiSparse. A host-resident tier for sparse-MLA decode. Under GPU pressure it spills KV pages to pinned host memory and serves top-k misses from a per-request GPU hot buffer. It is enabled through HiSparseConnector, exposes Prometheus counters, and shares a host cache across TP ranks.
Models. DeepSeek-V4.1-Flash stores its whole KV in MXFP8 through the FlashMLA V4.1 record on SM100. GLM-5.3-Flash arrives with expert-parallel load balancing. Also added: DeepSeek-V4-Flash-Vision-Exp (with ROCm and LoRA), K2-Horizon, Cohere Compass, Bailing V3 VL, and a DeepSeek-V4 CPU backend using AVX512/AMX kernels.
Quantization. Targeted online quantization through quantization_config.targets; online quantization of partially pre-quantized checkpoints; W4A16 DSA with the nvfp4_fp8_ds_mla KV cache; FlashInfer CuTeDSL NVFP4 W4A16 now the default over Marlin on SM100/103; NVFP4 in the torch linear backend; AutoRound at 2/3/5/6/7 bits on CUDA.
Breaking changes to check
- Scale-out endpoints.
/render,/derenderand/inference/v1/generateare no longer registered on plainvllm serveunless you pass--enable-scale-out.VLLM_ENABLE_SCALE_OUT_ENDPOINTSis gone.vllm launch renderand--tokens-onlystill register them. - GPTQ. Activation ordering (
g_idx) is removed, along with the related Marlin, GPTQ, CPU and RDNA3 kernels. Checkpoints that rely on it need re-quantizing. - YaRN. Vendor aliases no longer apply the scaling factor twice, so derived
max_model_lenfalls for some models: TeleChat3-36B-Thinking from 131072 to 32768, sarvam-105b from 5242880 to 131072. - Removed 0.29 deprecations.
VLLM_PREFIX_CACHE_RETENTION_INTERVAL,VLLM_MM_HASHER_ALGORITHM, theuse_fp4_indexer_cachealias, the ROCmCUDA_VISIBLE_DEVICESfallback (useHIP_VISIBLE_DEVICES), and theseq_lens_cpu/num_computed_tokens_cpumetadata properties. - Decode context parallelism. Attention backends must declare DCP support. ROCm standard attention, Triton, FlexAttention and TurboQuant now fail at backend selection with DCP.
- Audio. The default resampler moves from PyAV to torchaudio.
- Deprecations. The
allMamba cache mode falls back to Model Runner V1;python -m vllm.entrypoints.grpc_servergives way tovllm serve --grpc. MoRI-IO WRITE mode with hybrid KV groups needs--disable-hybrid-kv-cache-manager.
Security hardening
The notes list no CVE identifiers. They do list hardening: validation-error response bodies are bounded, closing an approximately 5,300x response amplification; client-supplied sparse embeddings are bounded before densification; request-controlled video sampling is capped for GLMGA and Qwen-VL; and cache_salt is validated before reaching LMCache so one request cannot take down the engine.
What defenders and operators should do
- Audit load balancers and orchestration that call the scale-out endpoints and add
--enable-scale-outdeliberately. Leaving them off is the safer default for exposed servers. - Grep launch scripts and manifests for the removed environment variables.
- Check GPTQ checkpoints for
g_idxreliance and re-check effectivemax_model_lenon YaRN models. - Pin the v0.30.0 image tag and canary before rollout.
- Our suggestion, not the release notes': if you run Fast Start, treat the daemon's IPC socket as a trust boundary between clients on the same GPU.