Alibaba's qwen4-max-preview runs on Token Plan keys only and retires after 25 Nov. Resellers price qwen4-max at $1.50/$4.50, so build on that id.
Alibaba Cloud opened a preview of its next Qwen flagship, qwen4-max-preview, at 10:00 on 11 November 2026 (UTC+8). It is reachable only with a Token Plan key, pay-as-you-go is not supported, and the model is retired after 24:00 on 25 November (UTC+8). The model that OpenRouter and OpenCode Go actually list and price is a different id, qwen4-max, at $1.50 per million input tokens and $4.50 per million output tokens. If you are building anything that has to outlive the preview window, target qwen4-max, not the preview id.
What the preview is
Alibaba's Model Studio page describes Qwen4-Max-Preview as the next-generation flagship multimodal model in the Qwen family. It follows the Qwen 4 training run Alibaba confirmed at Apsara in September (our earlier report).
The headline specs, all from Alibaba's preview page:
- Context: 1M tokens, with a maximum output of 393,216 tokens shared between thinking and the final answer.
- Input: text, image and video.
- Tools: function calling, web search and JSON schema output.
- Reasoning: thinking is on by default;
reasoning_efforttakeslow,mediumorxhigh, andxhighis the default. - Interface: compatible with OpenAI Chat Completions, OpenAI Responses and Anthropic Messages, so most existing clients need only a new base URL and key.
The base URL is https://token-plan.ap-southeast-1.maas.aliyuncs.com, and the key must come from Token Plan Personal or Token Plan Team. The page gives no price for the preview and says nothing about weights either way, so there are no open weights announced in the sources we read.
Two weeks, then it is gone
The window runs from 10:00 on 11 November to 24:00 on 25 November, both UTC+8. After that Alibaba retires the preview id. The same page names Qwen4-Max as the model that is available and recommended for production.
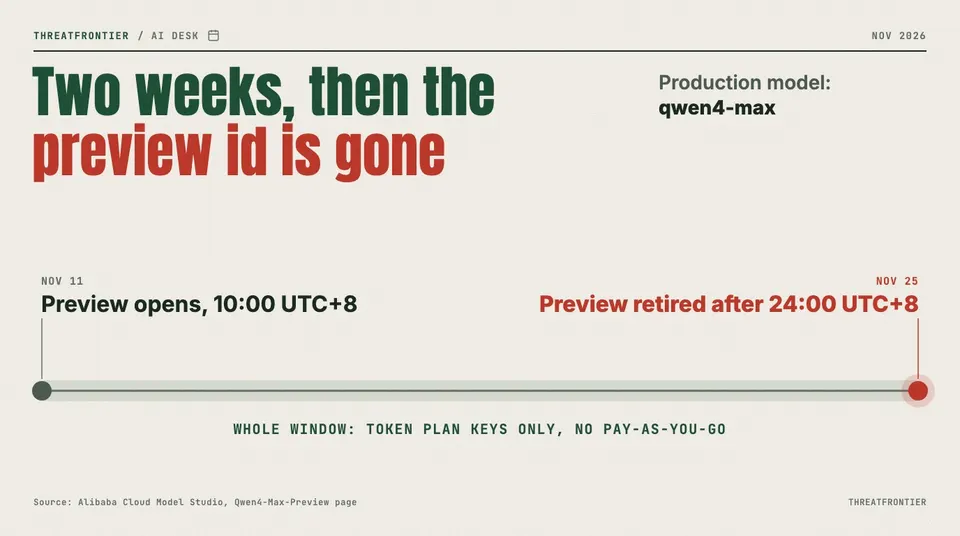
The qwen4-max-preview window, per Alibaba Cloud Model Studio. Alibaba names qwen4-max as the production model.
Anything that hard-codes qwen4-max-preview will stop working when the window closes. For a test harness or an eval run that is fine. For an agent, a product feature or a scheduled job, it is a bug with a known date.
The model resellers sell is qwen4-max
A correction to how this preview has been read: the third-party prices circulating for "Qwen4-Max" are for the production id, not the preview.
- OpenRouter lists
qwen/qwen4-max. Alibaba Cloud Int. serves it at $1.50 in and $4.50 out per million tokens; DeepInfra and NovitaAI list $1.413 in and $4.24 out. - OpenCode Go lists Qwen4 Max (
qwen4-max) at $1.50 input, $4.50 output, $0.075 cached read and $1.875 cached write per million tokens. Its plans are $10 a month (Go), $40 a month (Go Plus) and $20 per member a month (Go Teams), and it states zero data retention and no training on user data.
Neither page mentions a preview or a retirement date, and Alibaba's preview page gives no price. We could not confirm whether the preview and the production model are identical, so treat benchmark impressions from the preview as provisional for qwen4-max. For how OpenCode Go meters its plans, see our OpenCode Go $10 plan review; for the hosted-model alternative, our Ollama Pro vs Max pricing guide.
What builders should do
- Target
qwen4-maxin anything that ships. It is the id Alibaba recommends for production and the one OpenRouter and OpenCode Go sell. - Use the preview only for testing, and only with a Token Plan key. Do not route production traffic to
qwen4-max-preview. - Pin model ids and keep a fallback. A config that silently points at the preview will break after 25 November.
- Budget from the
qwen4-maxlistings ($1.50 / $4.50 per million tokens on OpenRouter's Alibaba route and on OpenCode Go), and check the provider's own pricing page before you commit. - Treat the 1M context and 393,216-token output as preview figures. Confirm them on
qwen4-maxbefore you design around them. - Do not assume open weights. None are announced in these sources.
Sources
- Alibaba Cloud Model Studio: Qwen4-Max-Preview: preview id, 1M context, Token Plan only, dates, no pay-as-you-go, production successor, API details
- OpenRouter: qwen/qwen4-max: provider prices for the production id; no preview or retirement notice
- OpenCode Go docs: Qwen4 Max at $1.50 / $4.50, plan prices and data terms