From 1 December Google sends gemini-2.5-pro calls to 3.8 Flash and 2.5 Flash to 3.5 Flash-Lite at the new rates, with breaking changes to thinking and sampling.
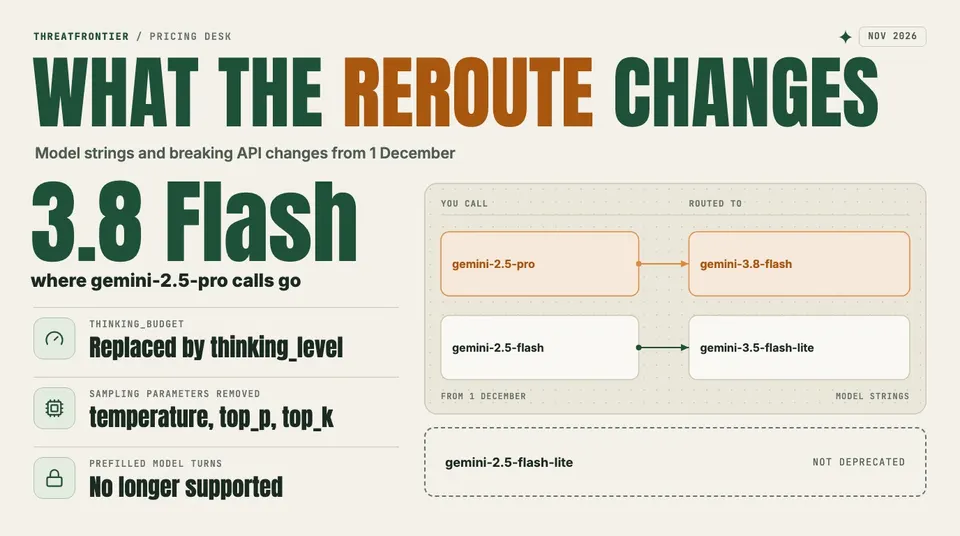
Starting 1 December 2026, Google will automatically send every Gemini API request for gemini-2.5-pro to gemini-3.8-flash, and every request for gemini-2.5-flash to gemini-3.5-flash-lite. Requests are billed at the new models' rates. Any developer still hard-coding either 2.5 model string is affected, and the replacement models carry breaking API changes that can make previously working calls fail. Google's deprecations page describes 1 December as the earliest possible date and says exact dates will be communicated with advance notice.
What Google announced
Google's release notes dated 2 November 2026 mark both models deprecated: they can no longer be selected in Google AI Studio, and API access is limited to users who have actively used them. The notes tell developers to update their model string before the reroute. gemini-2.5-flash-lite is not deprecated and stays available through the API until further notice, with no shutdown date announced.
What changes on the bill
| Model string you call | Routed to (from 1 Dec) | Input per 1M tokens | Output per 1M tokens |
|---|---|---|---|
gemini-2.5-pro today | n/a | $1.25 (prompts up to 200k), $2.50 above | $10.00 up to 200k, $15.00 above |
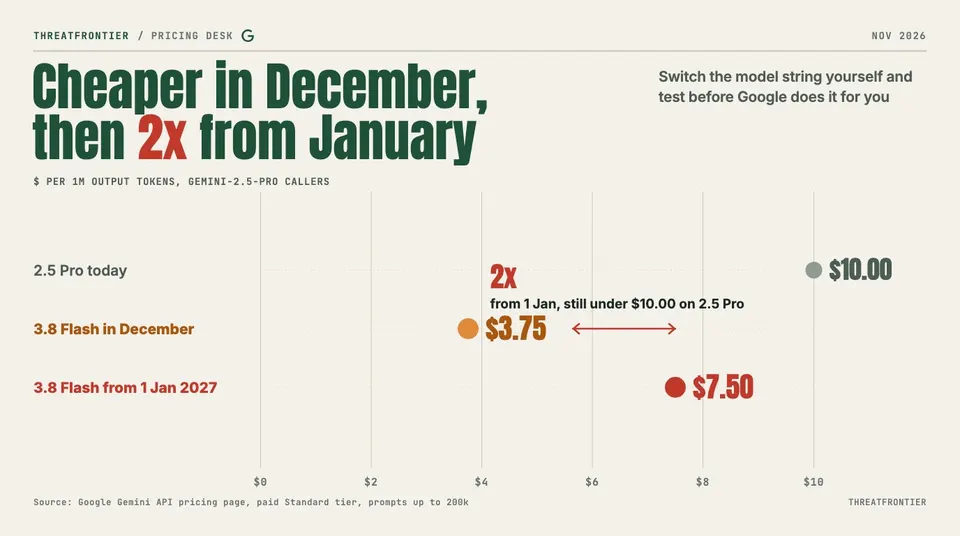
gemini-2.5-pro | gemini-3.8-flash | $0.75 through 31 Dec 2026, then $1.50 from 1 Jan 2027 | $3.75 through 31 Dec, then $7.50 from 1 Jan 2027 |
gemini-2.5-flash today | n/a | $0.30 text/image/video, $1.00 audio | $2.50 |
gemini-2.5-flash | gemini-3.5-flash-lite | $0.30 | $2.50 |
All figures are from Google's pricing page, paid Standard tier. For 2.5 Pro callers the rate is lower in December, and from 1 January 3.8 Flash input costs $1.50 against $1.25 for 2.5 Pro at prompts up to 200k tokens; output at $7.50 stays below $10.00. Long-prompt callers (over 200k) pay less on input either way. These are list prices per token: a different model may use a different number of thinking tokens, which are billed as output, so measure real traffic rather than assuming. For 2.5 Flash callers, the listed per-token rates are the same as 3.5 Flash-Lite's. We covered the same 1 January step for Google's voice model in Gemini 3.8 Flash TTS pricing doubles on 1 January 2027.
Where each model string goes on 1 December, and the breaking changes that come with it.
What changes in your code
Google's notes list the breaking changes for both reroutes: function calling and thought_signature validation; thinking_level replaces thinking_budget; sampling parameters are removed; prefilled model turns are no longer supported. The 3.8 Flash migration checklist adds detail:
- Replace
thinking_budgetwith the string enumthinking_level:low,mediumorhigh. The default ismedium.minimalis not supported and returns an error. - Remove
temperature,top_p,top_kandcandidate_count. The three sampling parameters were deprecated on 21 July 2026. - Remove prefilled model turns. Google advises moving multi-turn conversations to server-side
previous_interaction_id. - With
generateContent, everyFunctionResponsemust includecall_idandname. Place multimodal assets inside the response payload. - Preserve thought signatures between turns as the SDK guidance describes. We could not read the exact validation rules; check the migration guide.
What to do before 1 December
- Search your code and config for
gemini-2.5-proandgemini-2.5-flash, including gateways and environment variables. - Change the model string yourself to
gemini-3.8-flashorgemini-3.5-flash-liteand run your test suite against it now, rather than discovering failures after the automatic reroute. - Strip removed parameters and prefilled turns, and map each
thinking_budgetto athinking_level. - Budget for the 1 January 3.8 Flash price step.
- Pinning: Google's deprecations page documents no way to pin or opt out of the reroute. The only documented unaffected option is
gemini-2.5-flash-lite, which has no announced shutdown date. Expect that status to change at some point.
Note that Google also rerouted gemini-3.7-flash to gemini-3.8-flash and gemini-3.5-flash to gemini-3.6-flash on 8 October 2026, so Flash-family model strings are turning over quickly.