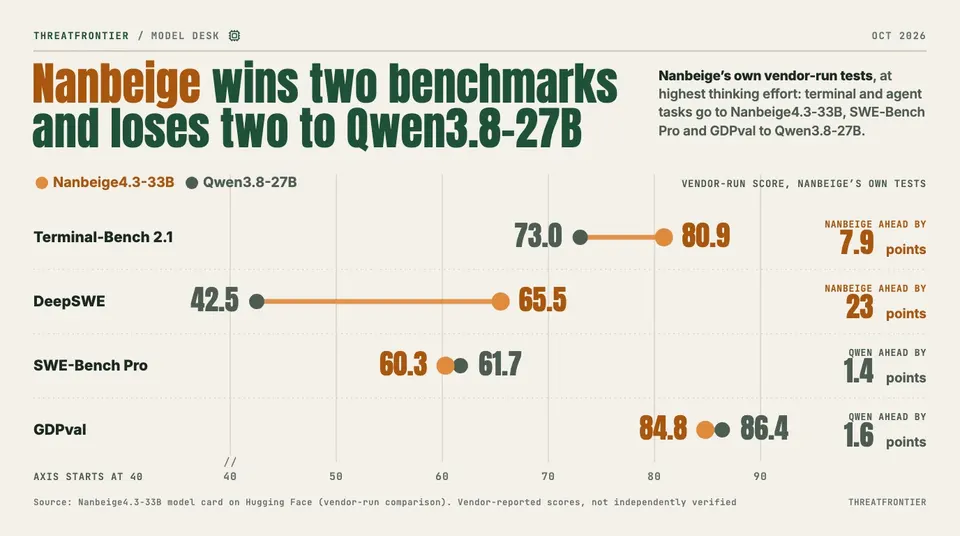
Nanbeige's new 33B open model leads Qwen3.8-27B on terminal and agent tasks in vendor-run tests, loses SWE-Bench Pro, and needs care to fit 16-32 GB.
Nanbeige released Nanbeige4.3-33B on Hugging Face on 24 October 2026 under the Apache-2.0 license. It is a dense model with 33,118,977,024 parameters, and the vendor calls it the "teacher" for a later round of small-model distillation. On its model card it beats Alibaba's Qwen3.8-27B on most agentic benchmarks, but not on all of them. Every benchmark figure in this article is Nanbeige's own, from a comparison Nanbeige ran. We found no independent reproduction.
What the vendor reports
The card compares Nanbeige4.3-33B with Qwen3.8-27B, Muse-Glimmer-30B and Gemma4-31B. Every model runs at its highest thinking effort, with the same inference hyperparameters and harness for each benchmark.
| Benchmark (vendor-run) | Nanbeige4.3-33B | Qwen3.8-27B |
|---|---|---|
| Terminal-Bench 2.1 (Terminus 2) | 80.9 | 73.0 |
| Terminal-Bench 4.0 | 23.8 | 6.3 |
| DeepSWE | 65.5 | 42.5 |
| SWE-Bench Pro | 60.3 | 61.7 |
| GDPval (revised rubrics) | 84.8 | 86.4 |
| Tau3-Bench | 48.8 | 48.5 |
| GPQA Diamond | 89.5 | 89.2 |
| AIME 2026 | 95.2 | 94.5 |
Qwen wins SWE-Bench Pro and GDPval. On Tau3-Bench, GPQA Diamond and AIME 2026 the gap is under a point, so read those as ties. The big gaps are on terminal and long-horizon agent tasks. Qwen's own card gives the same 73.0 for Terminal-Bench 2.1 and 61.7 for SWE-Bench Pro, so Nanbeige has not understated the Qwen figures. Qwen's harness notes differ, though: it ran SWE-Bench Pro in the Claude Code harness at 256K context.
Settings caveats
- Highest thinking effort. The comparison runs every model at maximum reasoning, so expect long outputs. The card recommends 65,536 max new tokens for agentic work and 262,144 for reasoning and chat. Qwen3.8 defaults to
reasoning_effortxhigh, so the two are comparable at their defaults. - preserve_thinking. Nanbeige produced its scores with
preserve_thinking=true. The card recommends true for multi-turn tool use, office and code-agent work, and false for general chat. Nanbeige is not alone here: Qwen3.8 also supportspreserve_thinkingand turns it on by default. If your runtime strips earlier reasoning, expect results below the published numbers for either model. - Sampling and tools. Nanbeige recommends temperature 1.0 and top_p 0.95 for agentic use, and 0.6 and 0.95 for reasoning and chat. It recommends
tool_call_format="xml", and its vLLM and SGLang examples use theqwen3reasoning parser and theqwen3_codertool parser. Qwen3.8's thinking mode uses temperature 1.0, top_p 0.95 and top_k 20. - Context. Nanbeige4.3-33B supports up to 524,288 tokens (512K). Long context costs memory, as the next section shows.
Which quant fits 16, 24 and 32 GB
The file sizes below are bartowski's published GGUF file sizes on Hugging Face, made with llama.cpp b11845. Everything else in this section is our estimate. In BF16 the weights take about 66.2 GB (estimate: 33.12 billion parameters at 2 bytes each). The KV cache is also our estimate, worked out from config.json (52 layers, 8 KV heads, head dimension 128): about 213 KB per token at f16, which is roughly 1.7 GB at 8K tokens, 7 GB at 32K and 14 GB at 64K (all estimates). Quantising the cache to q8_0 roughly halves it (estimate). Runtime overhead such as compute buffers and the display is not included; leave 1 to 2 GB for it.
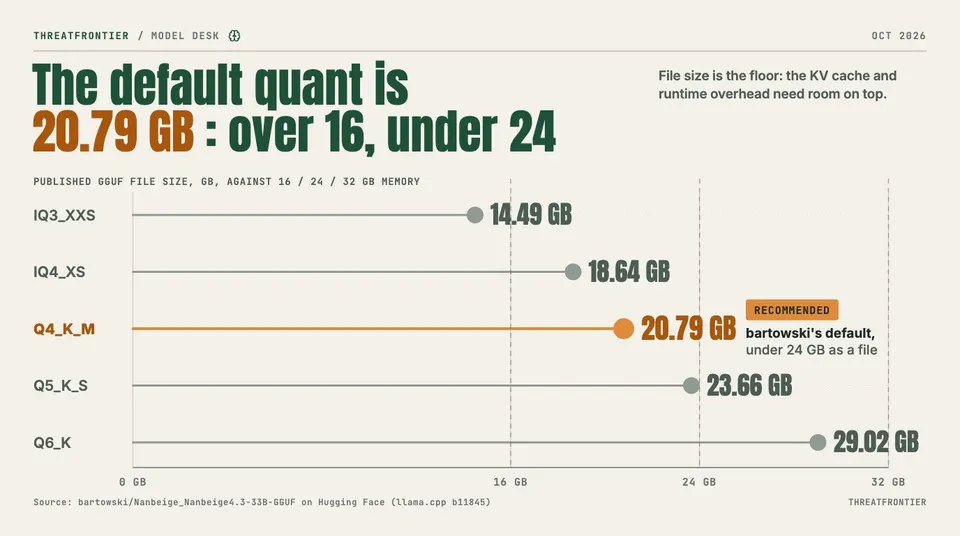
Published GGUF file sizes (bartowski, llama.cpp b11845) against common memory sizes; the KV cache and runtime overhead need room on top.
| Memory | Pick | File size (bartowski) | Left for KV cache (estimate) |
|---|---|---|---|
| 16 GB | IQ3_XXS (or Q2_K at 13.53 GB for more room) | 14.49 GB | about 1.5 GB before overhead: short context only, and we found no tests of what 3-bit quantisation does to an agentic model |
| 24 GB | IQ4_XS | 18.64 GB | about 3.5 to 4.5 GB after overhead: roughly 16K at f16, more with a q8_0 cache |
| 24 GB, tighter | Q4_K_M | 20.79 GB | about 1 to 2 GB after overhead: 8K or so |
| 32 GB | Q5_K_S | 23.66 GB | about 6 to 7 GB after overhead: 16K to 32K |
| 32 GB, max quality | Q6_K | 29.02 GB | about 1 to 2 GB after overhead: very short context |
Q4_K_M works out at about 5.0 bits per weight (estimate), and bartowski's page names it the recommended default. On a 16 GB machine this model is a stretch: the long-context agent work the benchmarks reflect needs far more memory than the weights alone. We found no published quality measurements for these quants, so the picks above are fit estimates, not quality rankings. For other models at this size, see our 24 GB Apple Silicon guide.
What to do
- Treat the headline numbers as vendor claims at maximum effort, and run your own task set before you switch from Qwen3.8-27B.
- Keep
preserve_thinkingon for agent loops, and make sure your client passes reasoning content back. - Budget the KV cache explicitly. Set context to what you need, not the 512K ceiling.
- Check who published any quant you download. The file sizes here are bartowski's; other third-party quants may differ.