llama-server now speaks OpenAI-style realtime transcription and text-to-speech. Here is how to run it with Voxtral Mini 4B, and what isn't ready yet.
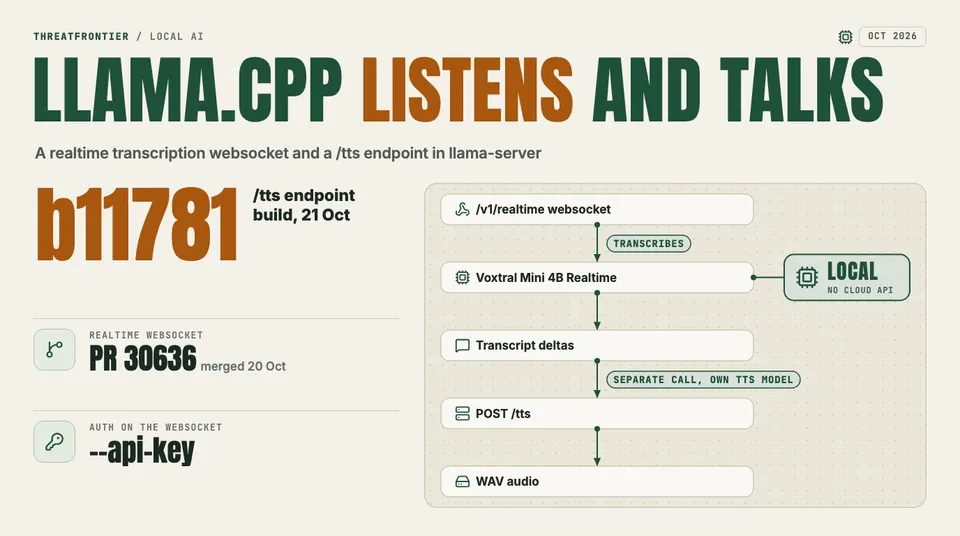
llama.cpp's server now speaks two speech APIs. PR 30636, merged on 20 October 2026, adds an OpenAI-compatible /v1/realtime websocket for transcription. PR 26603, also merged on 20 October, adds a POST /tts endpoint, and it ships in pre-release build b11781, published 21 October. Anyone running a local speech stack on llama-server is affected.
Realtime transcription
The websocket follows OpenAI's GA transcription session shape: session type transcription, with audio/pcm input. Clients append audio frames to the input buffer. The server answers with a session-created event, incremental transcript deltas, a committed-buffer event and completed events. In router mode the websocket is proxied to child servers.
The model the PR was tested with is Voxtral Mini 4B Realtime (2602), in the ggml-org GGUF repository, at Q8_0 on an RTX PRO 6000 in a container. The model card gives this launch line for Q4_K_M:
./llama-server -hf ggml-org/Voxtral-Mini-4B-Realtime-2602-GGUF:Q4_K_M
What hardware it needs
The model card lists no hardware requirements. It does list file sizes: Q4_K_M is 2.55 GB, Q8_0 is 3.66 GB and BF16 is 6.88 GB. The only tested hardware in the PR is the RTX PRO 6000 with Q8_0. Anything smaller is untested in the sources, so measure before you commit.
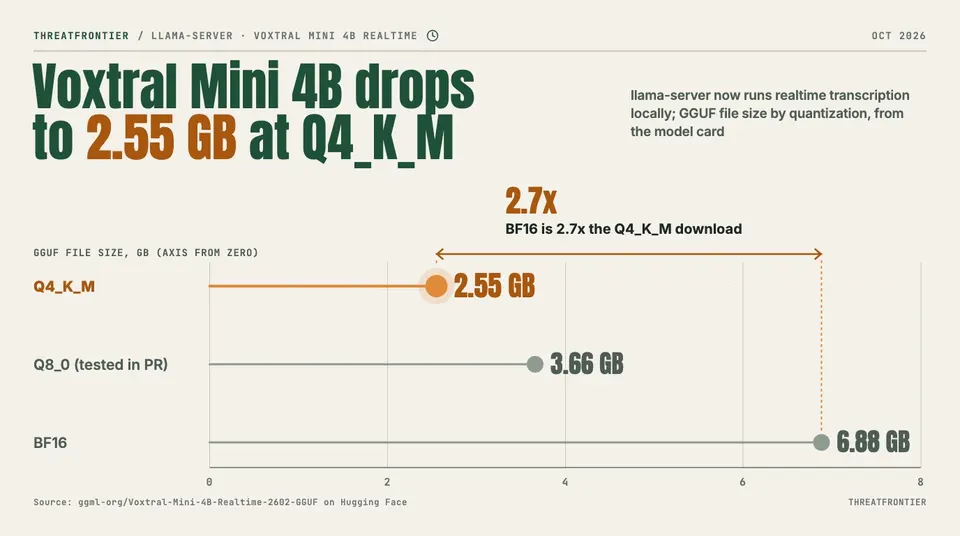
Voxtral Mini 4B Realtime GGUF sizes from the model card; the PR tested only Q8_0.
Voxtral Mini 4B Realtime GGUF sizes from the model card; the PR tested only Q8_0.
Limits to know
- The server reads audio at the model's sample rate and does not yet resample the 24 kHz audio that OpenAI-style clients send. Server-side resampling was deferred to a follow-up.
- Reviewers flagged the 16 MB maximum append size as a backlog risk, and
--sleep-idleas a risk for sessions. - Session length is roughly
n_ctxx 80 ms of audio, per a reviewer's estimate.
Securing the socket
The API key middleware now covers the websocket. A bad key returns 401 at the handshake. Bearer tokens, raw keys and X-Api-Key are accepted. If you expose the server beyond localhost, set --api-key.
The /tts endpoint
POST /tts takes JSON or multipart and returns audio, saved as WAV in the PR's examples. Voxtral Mini Realtime is a transcription model, so /tts needs a separate TTS model. The PR references Qwen3-TTS and pocket-tts; it does not give a full list or any enabling flags.
curl -X POST http://127.0.0.1:9931/tts \
    -H "Content-Type: application/json" \
    -d '{"input": "Hello, this is a test."}' \
    -o output.wav
curl -X POST http://127.0.0.1:9931/tts \
    -F "input=Hello, this is a test." \
    -F "speaker_ref=@/path/to/speaker-reference.wav;type=audio/wav" \
    -o output.wav
A --tts-speaker-dir flag, to pick voices by name, is listed as a future PR.
What to do
- Build b11781 or later for
/tts; check which build your package manager ships. - Start with Q4_K_M or Q8_0 for transcription and test latency on your own hardware.
- Put a resampler to the model's rate in front of OpenAI-style clients until server-side resampling lands.
- Set an API key before exposing either endpoint.