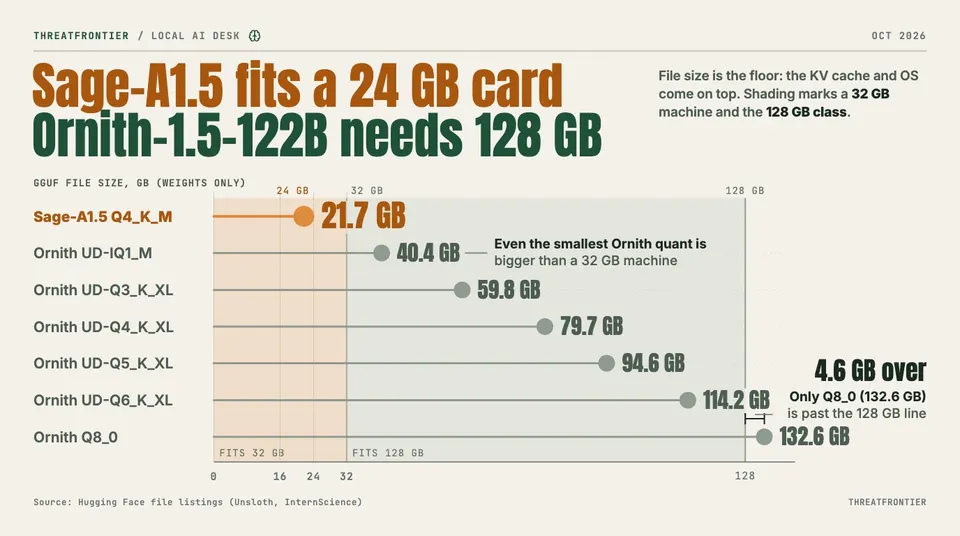
Sage-A1.5 fits a 24 GB card at 21.7 GB; Ornith-1.5-122B's smallest quant is 40.4 GB. The cards' 17-point SWE-bench Pro gap is a size mix-up.
Two open-weight coding models landed on Hugging Face within a day of each other in October 2026. Ornith-1.5-122B (MIT) is a 122B mixture-of-experts model whose card claims 84.5 on SWE-bench Verified and 80.0 on CyberGym. Sage-A1.5 (Apache 2.0) is a roughly 35B MoE finetune of Qwen3.6-35B-A3B from InternScience, with a card claim of 61.2 on SWE-bench Pro. Every score below is vendor-reported, from each model's own card. None has been independently reproduced in the sources we read.
The practical split is simple. Sage-A1.5 fits a 24 GB machine and a 32 GB machine at its published quant. Ornith-1.5-122B fits only the 128 GB class, because even its smallest quant is 40.4 GB.
What fits where
File size is the floor, not the requirement: the KV cache and the operating system come on top. The sizes below are decimal gigabytes from the Hugging Face file listings. The fit verdicts are our reading of those sizes, not vendor guidance, except where noted.
| Machine | Ornith-1.5-122B (Unsloth GGUF) | Sage-A1.5 (InternScience GGUF) |
|---|---|---|
| 16 GB | Nothing fits. Smallest quant, UD-IQ1_M, is 40.4 GB. | Q4_K_M is 21.7 GB. Needs CPU offload (the card says to lower -ngl), so expect it to be slow. |
| 24 GB | Nothing fits. | Q4_K_M at 21.7 GB. The card says a single 24 GB GPU "comfortably serves the model at moderate context lengths". |
| 32 GB | Nothing fits in memory. UD-IQ1_M (40.4 GB) and UD-IQ2_XXS (42.0 GB) still need offload. | Q4_K_M leaves about 10 GB for context. |
| 128 GB | UD-Q4_K_XL (79.7 GB) leaves about 48 GB. UD-Q5_K_XL (94.6 GB) leaves about 33 GB. UD-Q6_K_XL (114.2 GB) leaves about 14 GB, tight at long context. Q8_0 (132.6 GB) does not fit: it is 4.6 GB over the 128 GB line before any context. | Q4_K_M leaves most of the memory free. InternScience publishes only Q4_K_M; the card lists 29 community quants without recommending one. |
The full Ornith ladder, from Unsloth's listing: UD-IQ1_M 40.4 GB, UD-IQ2_XXS 42.0, UD-Q2_K_XL 44.5, UD-IQ3_XXS 49.5, UD-Q3_K_XL 59.8, UD-Q4_K_XL 79.7, UD-Q5_K_XL 94.6, UD-Q6_K_XL 114.2, Q8_0 132.6 and BF16 249.4. Ornith's own card says the model "serves on a single 80GB GPU". The 79.7 GB Q4_K_XL file alone nearly fills that, so on an 80 GB card expect little room for context.
Sage needs a recent runtime. Its GGUF uses the qwen35moe architecture, and older llama.cpp, Ollama or LM Studio builds will not load it.
The scores, and why the two cards disagree
The headline claims are not on a common footing. Ornith reports SWE-bench Verified 84.5, SWE-bench Pro 76.9, SWE-bench Multilingual 76.4 and CyberGym 80.0 for the 122B. Sage reports SWE-bench Pro 61.2 and Multilingual 72.7, and publishes no SWE-bench Verified or CyberGym figure at all. On the two SWE-bench tasks both cards cover, Ornith-122B leads by 15.7 points on Pro and 3.7 on Multilingual.
The apparent contradiction is a size mismatch, not a dispute. Sage's table has a column labelled only "Ornith-1.5" and shows SWE-bench Pro at 59.6. Ornith's 122B card shows 76.9. But 59.6 is the SWE-bench Pro score on Ornith's own card for Ornith-1.5-35B-A3B, a different and much smaller model. Three other numbers in Sage's column match that 35B-A3B card exactly: Multilingual 71.4, BrowseComp 67.6 and HLE with tools 33.4. Sage's card never states which Ornith it used, so the match is our inference, but four exact matches leave little room for coincidence.
Read that way, the like-for-like comparison is Sage-A1.5 against Ornith-1.5-35B-A3B. On Sage's own table Sage leads on Pro (61.2 vs 59.6), Multilingual (72.7 vs 71.4), BrowseComp (81.7 vs 67.6) and HLE with tools (55.1 vs 33.4). Ornith's 35B-A3B card also reports SWE-bench Verified at 79, a benchmark Sage does not report. The two Q4_K_M files are the same size to the tenth of a gigabyte, 21.7 GB each.
Three caveats apply. First, the harnesses differ: Sage ran SWE-bench with mini-SWE-agent and a 200K context, while Ornith used OpenHands with a 256K context, offline, and marked reward-hacking solutions as incorrect. Sage's card says it takes numbers from original technical reports where available and uses its own protocol otherwise, so some cells in its table may be its own runs. Second, Sage's SciCode figure for Ornith (39.5) and its IFBench figure (44.6) do not appear on the 35B-A3B card, so they were presumably produced by Sage's team. Third, the Ornith 122B card calls the model "the most lightweight member of the Ornith-1.5 family", yet the same collection lists 9B and 35B-A3B models. The card text is wrong or stale, and it is a reason to read the model tables, not the prose.
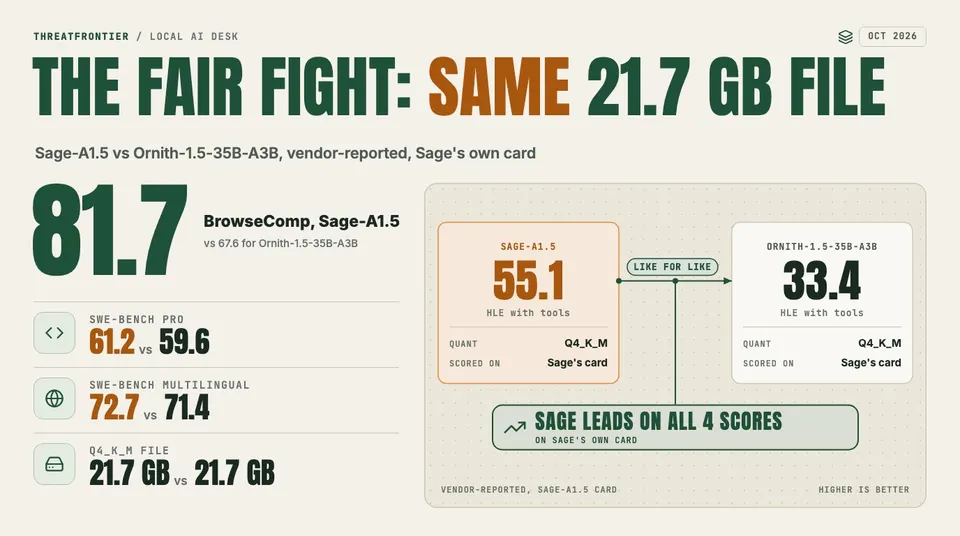
The fair comparison is Sage-A1.5 against Ornith-1.5-35B-A3B: same 21.7 GB file, and Sage ahead on every score in its own vendor-reported table.
What to do
- Pick by memory first. Under 40 GB of usable memory, Ornith-1.5-122B is out; compare Sage-A1.5 with Ornith-1.5-35B-A3B at Q4_K_M (21.7 GB each) on your own repositories.
- On 128 GB, UD-Q5_K_XL is the largest Ornith quant that leaves comfortable context headroom on file sizes alone. Test long-context runs before committing to Q6_K_XL.
- Do not quote the 84.5 or 80.0 figures as measured capability. They come from the vendor's own harness and have not been reproduced in anything we read. CyberGym in particular is a security-relevant score; treat 80.0 as a claim.
- Update llama.cpp, Ollama or LM Studio before loading either model. Sage's card warns older builds fail on
qwen35moe. - Use each card's sampling settings. For coding, Ornith recommends temperature 0.6, top_p 0.95, top_k 20 and presence_penalty 0.0; Sage lists temperature 1.0, top_p 0.95, top_k 20 and presence_penalty 1.5.