Reflection AI's Beam reports 80.9 on SWE-bench Verified and promises Apache 2.0 weights, but as of Oct 14 nothing is on Hugging Face and every number is vendor-reported.
Reflection AI announced Beam on October 5, 2026: a sparse mixture-of-experts model with 501 billion total parameters and 23 billion active per token, promised under the Apache 2.0 licence. As of October 14, there is nothing to download. Reflection says Beam is "undergoing final red-teaming and evaluations", with early access limited to a waitlist at platform.reflection.ai. Its announcement says the weights, technical report, model card and developer artifacts will be released "later this month". Teams planning to self-host should treat Apache 2.0 as a promise until a licence file and checkpoints appear.
Every benchmark figure below is vendor-reported, taken from Reflection's own announcement page.
What Reflection says Beam is
Beam is text-only, with 52 layers, mixed local and global attention, fine-grained routed experts and a residual stream using SandwichNorm, elementwise attention gating and FP32 accumulation. Pretraining used 23.8 trillion tokens in under four weeks on 6,144 NVIDIA GB300 NVL72 GPUs. Reinforcement learning ran four weeks on 10.5K GB300 GPUs, producing over 100 million rollouts at up to 256K tokens of context. Midtraining extends effective context to 1M tokens. A reasoning-effort setting trades response length for depth.
The headline efficiency claim is that on advanced reasoning benchmarks Beam scores comparably to GLM-5.2 "while using 3–4× less inference compute". Reflection's own chart presents this as an approximate FLOPs estimate that leaves out prefill and serving overhead, not a measured cost. We found no independent evaluation.
The vendor's table
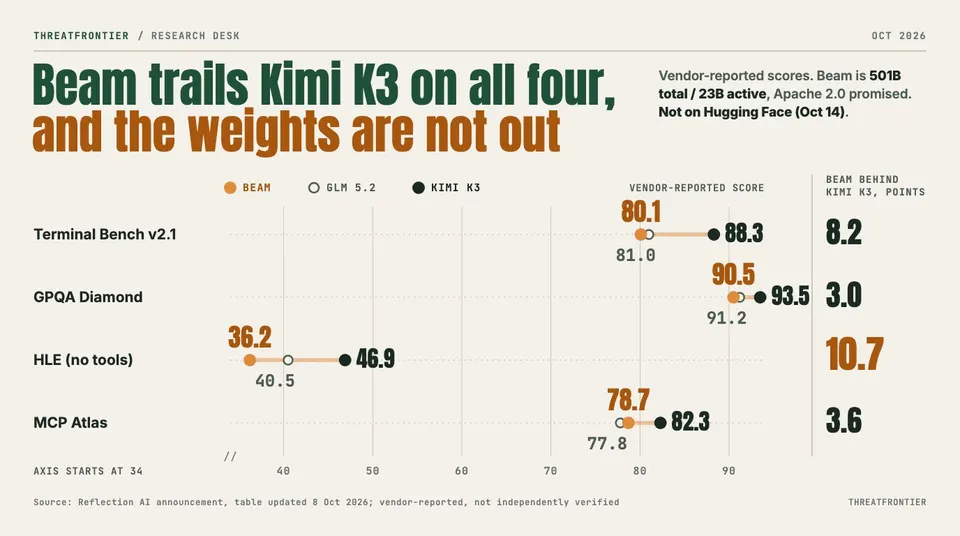
Reflection's table (updated October 8) reports Beam at 80.9 on SWE-bench Verified, against 77.6 for Inkling and 70.7 for Nemotron 3 Ultra. GLM 5.2 and Kimi K3 are marked "not reported" on that benchmark, so the 80.9 cannot be compared with them from this table. Where all are reported:
| Benchmark | Beam | GLM 5.2 | Kimi K3 | Inkling | Nemotron 3 Ultra |
|---|---|---|---|---|---|
| Terminal Bench v2.1 | 80.1 | 81.0 | 88.3 | 63.8 | 56.4 |
| GPQA Diamond | 90.5 | 91.2 | 93.5 | 87.2 | 87.0 |
| HLE (no tools) | 36.2 | 40.5 | 46.9 | 29.7 | 26.7 |
| MCP Atlas | 78.7 | 77.8 | 82.3 | 76.0 | 63.1 |
| SWE Bench Pro v1 | 65.5 | 62.1 | n/r | 54.3 | 46.4 |
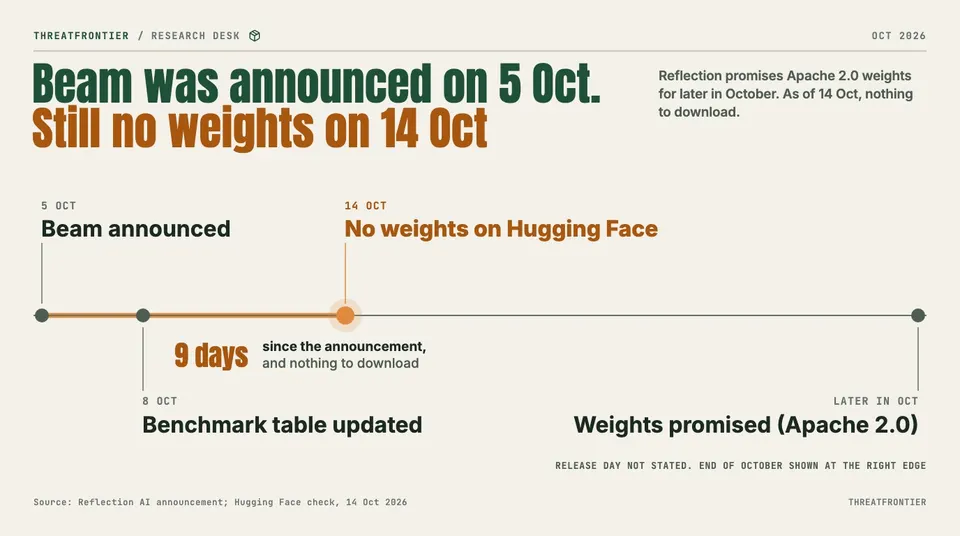
Beam's release timeline as of October 14, 2026. Dates from Reflection's announcement and our Hugging Face check.
The pattern: Beam clearly beats Inkling and Nemotron 3 Ultra on every row, roughly matches GLM 5.2 (ahead on MCP Atlas and SWE Bench Pro v1, behind on Terminal Bench, GPQA and HLE), and trails Kimi K3 wherever K3 is reported. Reflection itself says Kimi K3 remains ahead on raw capability and that Beam's advantage is inference efficiency. The table was chosen by the vendor and also includes models not discussed here.
What to do
- Do not plan a deployment around Beam yet. Hugging Face searches on October 14 returned no Beam model and the huggingface.co/reflection-ai page returned 404; the org name for the eventual release is unconfirmed.
- When weights land, verify the licence file is Apache 2.0, check for any acceptable-use addenda, and size hardware: 501B parameters need multi-GPU memory even with 23B active. Reflection has not published inference requirements or pricing.
- Wait for independent runs of SWE-bench Verified and the agentic suites before relying on the vendor numbers, particularly for GLM 5.2 and Kimi K3, where the key coding row is blank.
- Check Reflection's own safety evaluation in the model card once released, since red-teaming is still under way.
Sources
- https://reflection.ai/blog/introducing-beam
- https://letsdatascience.com/news/reflection-introduces-beam-open-weight-reasoning-model-b6a0e32f
- https://www.vktr.com/ai-platforms/reflection-ai-unveils-beam-a-501b-open-weight-model/
- https://huggingface.co/api/models?search=reflection%20beam&limit=20
- https://huggingface.co/reflection-ai