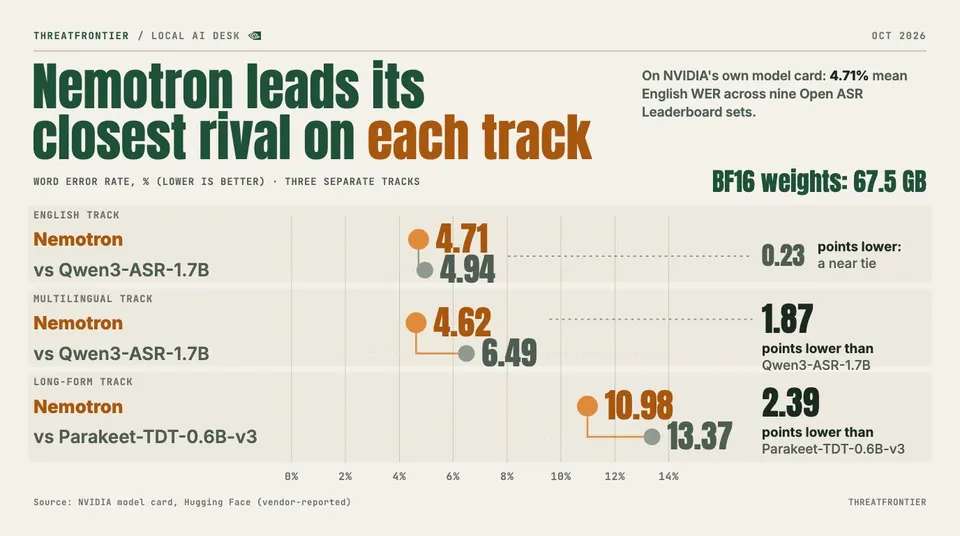
NVIDIA's open-weight speech model beats Qwen3-ASR and Parakeet on its own card, but BF16 weights are 67.5 GB. Which formats fit 16, 24 and 32 GB cards.
NVIDIA released Nemotron 3.5 Transcribe 30B-A4B on 28 October 2026, an open-weight speech model for offline transcription in 40 languages. Its model card reports a 4.71% mean word error rate across nine English Open ASR Leaderboard sets. Anyone choosing a local speech-to-text stack, from self-hosters to enterprises wary of sending audio to a cloud API, now has a new reference point. The hardware bar is high: the reference setup is a single 80 GB H100.
What NVIDIA released
The model is a Mamba-2/Transformer hybrid mixture-of-experts speech LLM built on Nemotron 3.5 Lightning 30B-A3B, with an audio encoder of about 800M parameters. The card lists 34B parameters in total and 4.3B active, including the encoder. It takes recordings up to one hour with a 65,536-token context. The licence is OpenMDW-1.1, which NVIDIA describes as ready for commercial and non-commercial use. This is an offline model, not a live-captioning one.
How it compares
On the nine English sets, Nemotron scores 4.71 against 4.94 for Qwen3-ASR-1.7B, a gap of 0.23 points. On the card's multilingual mean over seven languages it scores 4.62 against 6.49 for Qwen3-ASR-1.7B. On the long-form track it scores 10.98 against 13.37 for Parakeet-TDT-0.6B-v3. The card gives no Parakeet figure for the English or multilingual tracks, so we cannot compare them.
Per-set English results vary a lot: 1.09 on LibriSpeech test-clean and 1.84 on VoxPopuli, but 7.81 on AMI meetings and 11.00 on URGENT24. The numbers are NVIDIA's own, captured on 12 October 2026. One secondary source, ai-tldr, reports a 5.33% average on the Hugging Face English leaderboard instead; we could not reconcile the two figures. Treat 4.71 as the vendor claim and test on your own audio. The card itself warns of substitutions, deletions, repetitions and hallucinated speech, especially on long recordings, overlapping speakers and noise.
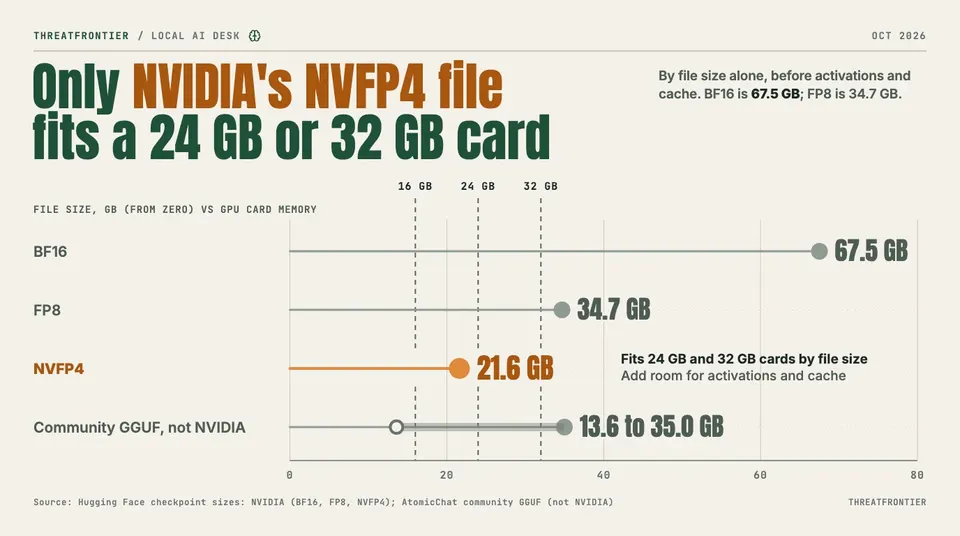
By file size alone, only NVIDIA's NVFP4 checkpoint (21.6 GB) fits a 24 GB or 32 GB card, before room for activations and cache.
What it takes to run locally
The card gives no VRAM figure per precision, so the numbers below are checkpoint file sizes from Hugging Face. Add room for activations and cache.
| Format | Size | Source |
|---|---|---|
| BF16 | 67.5 GB | NVIDIA |
| FP8 | 34.7 GB | NVIDIA |
| NVFP4 | 21.6 GB | NVIDIA |
| Community GGUF, Q2_0_M to Q8_0 | 13.6 to 35.0 GB | AtomicChat (not NVIDIA) |
By file size alone, a 16 GB card fits only the most aggressive community 2-bit GGUF (13.6 or 15.6 GB), with little headroom and no published accuracy data for it. A 24 GB card fits NVFP4 or a 4-bit GGUF (19.7 GB), but NVIDIA lists NVFP4 on Blackwell parts such as the RTX 5090 and DGX Spark. A 32 GB card, such as an RTX 5090, fits NVFP4 comfortably. Whether the community GGUFs match NVIDIA's WER is unverified.
NVIDIA's hardware table lists the DGX Spark (GB10) for BF16, FP8 and NVFP4. BF16 at 67.5 GB is a tight fit in its memory, so FP8 or NVFP4 is the practical choice. The H100 and H200 take BF16 and FP8; the A100 80GB takes BF16; the L40S 48GB takes FP8.
Inference needs vLLM 0.32.0 with the latest NeMo Speech branch and the nemo_speechlm plugin, which exposes an OpenAI-compatible server. SGLang-Omni 0.2.0 also serves the model but lacks word timestamps and speaker attribution.
What to do
- Run your own audio, including noisy and multi-speaker recordings, before replacing an existing engine.
- Start with NVFP4 or FP8 for local tests; use BF16 only on 80 GB parts.
- Treat community GGUF builds as unvetted third-party files and pull them from a source you trust.
- If the server is reachable from a network, put authentication in front of the vLLM endpoint.
Sources
- https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Transcribe-30B-A4B
- https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Transcribe-30B-A4B-FP8
- https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Transcribe-30B-A4B-NVFP4
- https://huggingface.co/AtomicChat/NVIDIA-Nemotron-3.5-Transcribe-30B-A4B-GGUF
- https://ai-tldr.dev/releases/nvidia-nemotron-3-5-transcribe/index.md