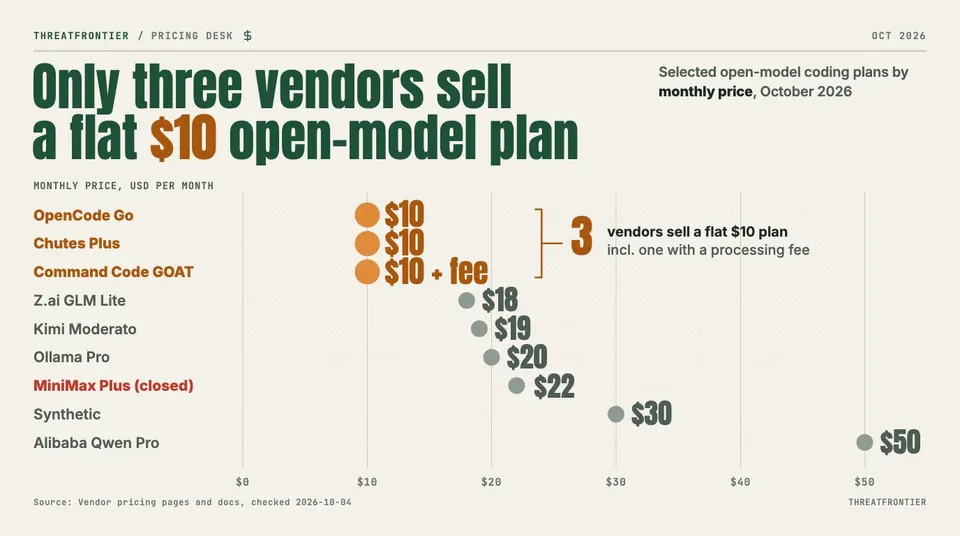
Only OpenCode Go, Chutes Plus and Command Code GOAT list a flat $10 tier. Every vendor price and cap here was read on its own page on 2026-10-04.
Update, 16 Nov 2026: OpenCode Go now sells Go Plus at $40 and Go Teams at $20 per member alongside the $10 Go, publishes per-model request estimates for each plan, raised DeepSeek V4.1 Flash to a $100 monthly cap (216,670 requests a month on Go) and added Qwen4 Max and Kimi K3.1 Pro. We rechecked OpenCode Go, Z.ai, Ollama and Alibaba on 2026-11-16; Z.ai and Ollama prices are unchanged.
Every other price and limit below was read on the vendor's own page on 2026-10-04. Figures marked "computed" are our arithmetic, with the formula shown. Anything we could not confirm on a primary source is marked UNVERIFIED and left out of the comparison.
Three vendors sell a flat $10 monthly plan that reaches open-weight coding models: OpenCode Go, Chutes Plus and Command Code GOAT. Z.ai, Xiaomi, Ollama, Kimi, MiniMax and Alibaba sell nothing at $10. Their cheapest current tier sits below ($6 MiMo Lite) or above it ($16 to $50), and MiniMax and Alibaba have closed their old entry tiers. DeepSeek, OpenRouter, Fireworks, Together and Cerebras sell no flat plan at all.
Summary table
| Plan | Monthly price | Cap model | Open-weight models named by the vendor | Checked |
|---|---|---|---|---|
| OpenCode Go | $10 (Go Plus $40, Teams $20 per member) | Dollar caps: 20% per 5h, 50% per week of a per-model monthly limit | GLM, Kimi, MiMo, MiniMax, Qwen, DeepSeek, Hy, LongCat | 2026-11-16 |
| Chutes Plus | $10 | Daily request quota (number UNVERIFIED) | GLM, Kimi, DeepSeek, Qwen | 2026-10-04 |
| Command Code GOAT | $10 + processing fee | $70 monthly credits, ~75K requests | GLM-5.2, Qwen 3.8 27B, DeepSeek V4.1 Flash, plus 30 more | 2026-10-04 |
| Xiaomi MiMo Lite | $6 | 60M credits, no 5-hour limit | MiMo | 2026-10-04 |
| Z.ai GLM Lite | $18 | 2,000 credits per 5h, 10,000 per week | GLM-5.3, GLM-5.3-Flash | 2026-11-16 |
| Kimi Moderato | $19 | Shared credit pool, 60 agent credits | Kimi K3 | 2026-10-04 |
| Ollama Pro | $20 | $60 usage credits | Many | 2026-11-16 |
| Synthetic | $30 | 500 requests per 5h | Kimi-K3, GLM-5.3, DeepSeek-V4.1-Flash | 2026-10-04 |
| Alibaba Pro | $50 | 6,000 per 5h, 45,000 per week, 90,000 per month | Qwen, Kimi, GLM, MiniMax | 2026-11-16 |
Price ladder, lowest to highest: Ollama Free $0, Command Code Go $1, MiMo Lite $6, then three plans at $10, MiMo Standard $16, GLM Lite $18, Kimi Moderato $19, Chutes Pro and Ollama Pro $20, MiniMax Plus $22 (closed to new buyers), Synthetic $30, OpenCode Go Plus $40. OpenCode Go Teams is $20 per member.
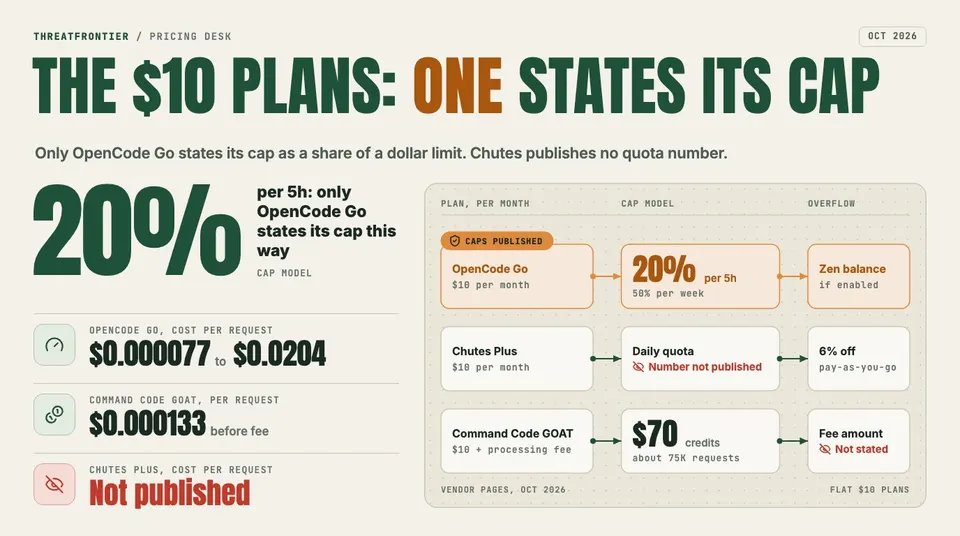
The three $10 plans compared on what each vendor publishes (vendor pages, checked 2026-10-04).
OpenCode Go: $10, the most transparent caps
- Price: Go $10 per month, Go Plus $40, Go Teams $20 per member per month. Go and Go Plus are for single-member workspaces; Teams gives each member caps $5 above Go on every model.
- Models: the docs now list 34, including GLM-5.3, Kimi K3, Kimi K3.1 Pro, MiMo-V2.6, MiniMax M3, Qwen3.8, Qwen4 Max and DeepSeek V4.1 Flash. Some are not open-weight: Grok 4.7, GPT 6 Luna, GPT 5.6 Luna, Claude Haiku 5.5 and Gemini 4 Argon are on the list, and the two Muse Spark entries are limited to certain regions.
- Caps: each model has a monthly dollar limit that depends on the plan, from $15 to $100 on Go. The 5-hour window is 20% of it, the week is 50%. Go Plus raises the limits unevenly: 4x on Kimi K3, Kimi K3.1 Pro and Qwen4 Max, 8x on GLM-5.3, 3x on GLM-5.3-Flash and MiniMax M3, 2x on DeepSeek V4.1 Flash.
- Requests on Go (per 5h / week / month): DeepSeek V4.1 Flash 43,330 / 108,330 / 216,670. GLM-5.3-Flash 6,320 / 15,790 / 31,580. MiniMax M3 3,200 / 8,000 / 16,000. Qwen4 Max 460 / 1,160 / 2,310. GLM-5.3 220 / 540 / 1,080. Kimi K3.1 Pro 147 / 368 / 735. Kimi K3 110 / 250 / 490.
- Requests on Go Plus (per month): DeepSeek V4.1 Flash 433,330. GLM-5.3-Flash 94,740. MiniMax M3 48,000. Qwen4 Max 9,240. GLM-5.3 8,640. Kimi K3.1 Pro 2,941. Kimi K3 1,960.
- List prices per 1M tokens: GLM-5.3-Flash $0.15 in / $0.50 out. Qwen4 Max $1.50 / $4.50. Kimi K3.1 Pro $2.00 / $10.00. Kimi K3 $3.00 / $15.00. DeepSeek V4.1 Flash $0.15 / $0.60 off-peak, $0.30 / $1.20 peak.
- Computed cost per request: $10 / 216,670 = $0.000046 on DeepSeek V4.1 Flash. $10 / 2,310 = $0.0043 on Qwen4 Max. $10 / 735 = $0.0136 on Kimi K3.1 Pro. $10 / 490 = $0.0204 on Kimi K3. The same $10 buys a 442-fold different number of requests depending on model (216,670 / 490).
- Computed, Go Plus vs Go: Go Plus costs 4x as much. It halves the cost per request on GLM-5.3 ($40 / 8,640 = $0.0046 vs $0.0093), matches Go on Kimi K3, Kimi K3.1 Pro and Qwen4 Max, and doubles it on DeepSeek V4.1 Flash ($40 / 433,330 = $0.000092).
- Computed value multiple: the $100 DeepSeek V4.1 Flash limit on a $10 plan is 10x; a $60 limit is 6.0x; a $15 limit is 1.5x. Frontier-priced models such as Kimi K3, Kimi K3.1 Pro, Qwen4 Max and GLM-5.3 are the $15 ones.
- Overflow: the docs now call it Extra Usage. With it on, requests past the limits draw on your pay-as-you-go Console balance instead of being blocked; Go Teams starts with it on. In October Zen passed card fees through at 4.4% + $0.30 per transaction.
- Tools: validated with OpenCode, Claude Code, Codex, Hermes, ZCode, Pi, jcode and Kilo Code CLI. The docs flag DeepSeek Harness, GitHub Copilot Chat, Kimi Code and MiMo Code as having incomplete session support. Apps that send no session ID cannot use Go models.
- Go vs Zen: Go is flat monthly with per-model caps. Zen is per-token credits with no caps.
- Qwen4 Max: the production
qwen4-maxid is the one Go sells. Alibaba'sqwen4-max-previewruns only on Token Plan keys and is retired after 25 November; see our Qwen4-Max preview report.
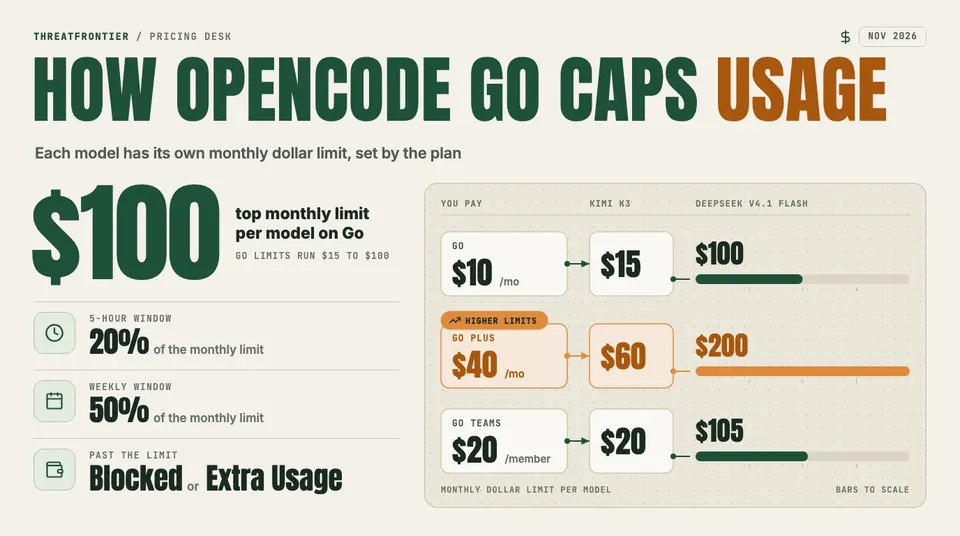
How OpenCode Go's per-model dollar limits work on each plan, and what happens at the limit (opencode.ai/docs/go, checked 2026-11-16).
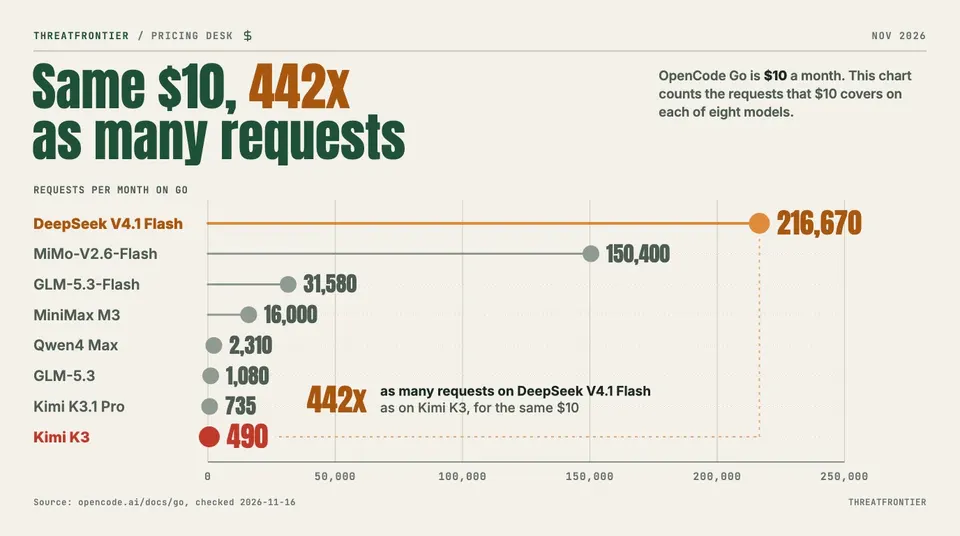
Requests per month on OpenCode Go by model (opencode.ai/docs/go, checked 2026-11-16). The 442x gap is computed as 216,670 / 490.
Chutes Plus: $10, but the quota is not published
- Price: Plus $10 per month, Pro $20. Plus gets 6% off pay-as-you-go rates beyond the quota, Pro 10%.
- Quota: the page says "bundled daily quota" and links to plan limits. We could not retrieve a number, so the daily request count is UNVERIFIED.
- Pay-as-you-go rates per 1M tokens (in / out): DeepSeek-V4-Flash-0731 $0.44 / $1.32. Kimi K2.6 $0.50 / $2.85. GLM-5.2 $1.25 / $3.95. Qwen3.8-27B $0.24 / $2.20. Kimi-K3 $3.00 / $15.00.
- Computed session cost: Chutes' own estimator defines an intense four-hour coding session as 1.5M input and 90K output tokens. Formula: in x price_in + out x price_out. DeepSeek-V4-Flash-0731 costs $0.78 (12.8 sessions per $10). Kimi K2.6 costs $1.01 (9.9 sessions per $10).
- Privacy: the featured models run on confidential TEE compute.
Command Code GOAT: $10 plus a fee that is not stated
- Price: $10 per month plus a "processing fee". The page gives no amount, so the all-in price is UNVERIFIED.
- What you get: $70 of monthly credits (up to about $100 of usage with deals) and roughly 75K requests.
- Models: $70 allowance on GLM-5.2, Tencent Hy3 and Qwen 3.8 27B; $60 on DeepSeek V4.1 Flash; 30 more models including Kimi, MiniMax, MiMo and Nemotron. Several stealth and Ling models cost no credits. GPT-5.6 Luna, Grok 4.5 and Qwen Max and Plus are closed-source models included on every plan.
- Effective usage: MiniMax M3 credits stretch up to 2x (the page shows $47 on GOAT); MiMo V2.5 up to 5x (about $100).
- Computed: $10 / 75,000 = $0.000133 per request, before the fee. Credits per dollar: 7.0x on GOAT, 10x on the $1 Go tier, 4.0x on Pro ($20 for $80).
- Ladder: Go $1 ($10 credits, ~9K requests), GOAT $10, Pro $20 ($80, ~100K), Max 10x $100 ($150, ~219K), Max 20x $200 ($300, ~437K).
Z.ai GLM Coding Plan: from $18
- Price: Lite $18, Pro $72, Max $160 per month. Quarterly: $48.60, $194.40, $432. Annual: $172.80, $691.20, $1,536. Computed: Lite annual is $14.40 per month, Max annual $128.
- Credits: Lite 2,000 per 5 hours and 10,000 per week; Pro 12,000 and 60,000; Max 28,000 and 140,000.
- Weekly token allowance on GLM-5.3 at 95% cache hits: Lite 48 to 97M, Pro 290 to 580M, Max 676 to 1,352M. The low end is peak hours and the high end is off-peak. On GLM-5.3-Flash Lite gets 146 to 292M.
- Computed price per 1M tokens (GLM-5.3): $18 / (48M x 52/12) = $0.086 at peak, $0.043 off-peak. Pro is $0.057 to $0.029. Max is $0.055 to $0.027. GLM-5.3 API list price is $1.40 in and $4.40 out.
- Peak hours: Monday to Friday 14:00 to 18:00 Singapore time. Off-peak is charged at half the credit rate. The promotion that charged all usage at the off-peak rate ran from 2026-09-25 to 2026-10-07 and has ended; tiers, credits and allowances were unchanged on 2026-11-16.
- Models and tools: GLM-5.3 and GLM-5.3-Flash; Claude Code, Cline and OpenCode; web search, web reader and Zread MCP tools. The terms bar using the quota for your own apps, bots or SaaS, and bar resale.
- Renewal: the terms say a renewal is charged at the price shown on the day of the charge, not your original price. A 50% discount exists only for legacy subscribers migrating after 2026-04-30. We found no public new-user intro discount.
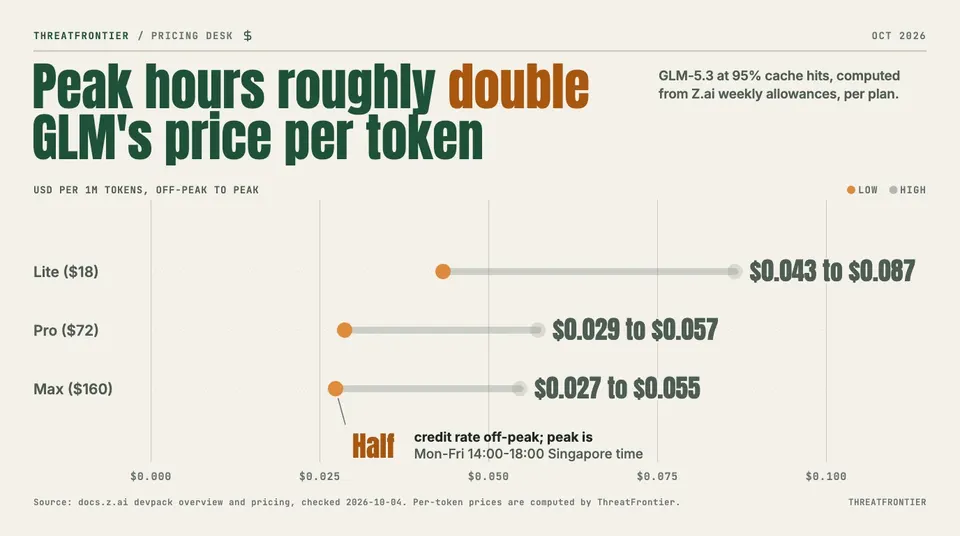
GLM Coding Plan price per 1M tokens, off-peak vs peak. Computed by ThreatFrontier from Z.ai's weekly allowances.
Xiaomi MiMo Token Plan: $6 or $16
- Price (overseas): Lite $6, Standard $16, Pro $50, Max $100. A 12% discount applies to the first purchase only (Lite $5.28, computed).
- Credits: Lite 60M (about 120 medium to complex tasks), Standard 200M (400), Pro 700M (1,400), Max 1.6B (3,200). Computed cost per task: $0.050, $0.040, $0.036, $0.031.
- No 5-hour limit. Credits are consumed at a multiple of tokens: 1x for mimo-v2-omni, 2x for mimo-v2-pro up to 256K context, 4x beyond that.
- Tools: Claude Code, OpenClaw, OpenCode, Kilo Code and Cline.
- Caveat: this is Xiaomi's launch post. It names the older v2 models. The current subscription page is a JavaScript app that returned no content, so the v2.6 plan table and credit counts are UNVERIFIED. MiMo-V2.6 models are available through OpenCode Go at $0.14 / $0.28 per 1M (Flash).
Alibaba Qwen Coding Plan: $50 only
- Price: Pro $50 per month. The cheaper Lite tier closed to new subscriptions on 2026-03-20 and renewals and upgrades ended on 2026-04-13. Alibaba's docs now label the product "Coding Plan (legacy)" beside a separate Token Plan, and Pro slots are limited, first come first served, with new slots added daily.
- Limits: 6,000 requests per 5 hours, 45,000 per week, 90,000 per month. Computed: $50 / 90,000 = $0.00056 per request.
- Models: qwen3.7-plus, qwen3.6-plus, kimi-k2.5, glm-5, MiniMax-M2.5 recommended; also qwen3.5-plus. Models not on that list are not supported, and Qwen4 is not on it.
- Rules: interactive tools only. No scripts or backends on the plan key.
Ollama Cloud, Kimi, MiniMax, Synthetic
- Ollama: Free $0 (pay-as-you-go credits), Pro $20 or $200 a year ($16.67 a month) with $60 of credits, Max $100 with $300 and 10 concurrent requests. Computed: credits are 3.0x the fee on both paid tiers. Per 1M tokens: glm-5.3 $1.40 / $4.40, deepseek-v4.1-flash $0.30 / $1.20, kimi-k3 $3.00 / $15.00, kimi-k3.1-pro $2.00 / $10.00. Unchanged on 2026-11-16, apart from a new Team tier at $500 with $1,000 of shared credits.
- Kimi: USD tiers are Moderato $19, Allegretto $39, Allegro $99, Vivace $199. Annual Moderato is $180 ($15 a month). Kimi Code is in every tier. No numeric Kimi Code cap was published on the pages we read.
- MiniMax: Token Plan Plus $22, Max $55, Ultra $132, with 5-hour and weekly windows. Token Plan is closed to new purchases and replaced by M Plan tiers Go, Explore (3x) and Build (7.5x). The M Plan dollar prices are UNVERIFIED.
- Synthetic: $30 a month or $1 a day, 500 requests per 5 hours, one concurrent request per model. No $10 tier.
No flat plan: DeepSeek, OpenRouter, Fireworks, Together, Cerebras
- DeepSeek API: pay-as-you-go. V4.1 Flash is $0.15 in / $0.60 out off-peak, $0.30 / $1.20 at peak. V4-Pro is $0.66 / $1.98 off-peak. Concurrency 2,500 (Flash) and 500 (Pro). Computed: the four-hour session above costs $0.558 at peak and $0.279 off-peak, so $10 of balance covers 17.9 to 35.8 sessions.
- OpenRouter: 50 requests a day on Free; Standard adds a 5.5% platform fee.
- Cerebras: a one-time $5 credit that expires in 30 days. Fireworks and Together: per-token only on the pages we read. Their rate tables did not load, so model prices are UNVERIFIED.
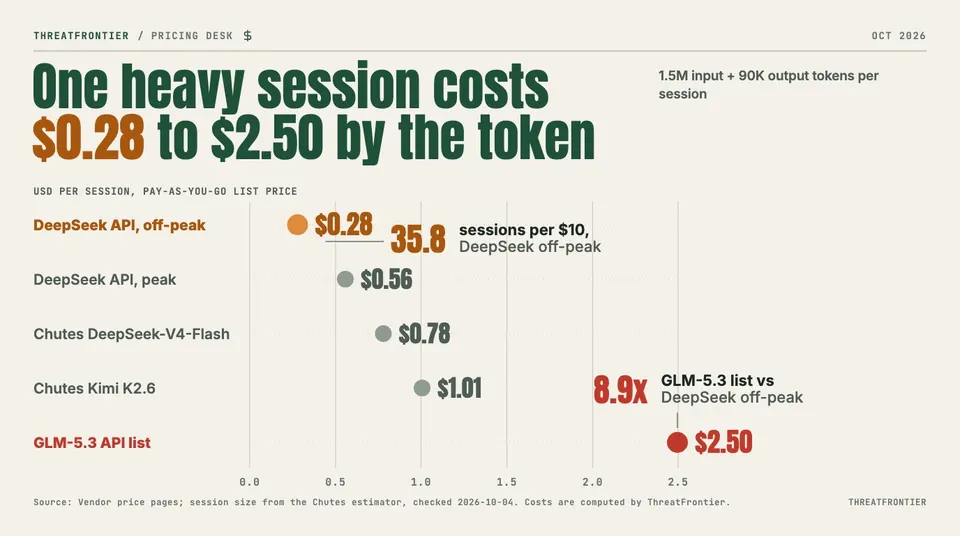
Cost of one heavy session at pay-as-you-go list prices. Session size is from the Chutes estimator; costs are computed by ThreatFrontier.
Which one for which developer
- Heavy daily agent use on a cheap model: OpenCode Go with DeepSeek V4.1 Flash (216,670 requests a month) or MiMo-V2.6-Flash (150,400).
- Frontier open models, light use: Kimi K3 gets only 490 requests a month on Go and Kimi K3.1 Pro 735. Qwen4 Max stretches further at 2,310. Otherwise check Chutes or an API balance.
- Heavy GLM-5.3 use through OpenCode: Go Plus at $40 gives 8,640 GLM-5.3 requests a month, 8x Go for 4x the price. On the other models Plus is no better per dollar.
- Many models, one wallet: Command Code GOAT, after you find out the fee.
- GLM only, Claude Code or Cline: GLM Lite at $18, or $14.40 annual.
- Occasional use: a $10 top-up at DeepSeek is 18 to 36 heavy sessions with no subscription.
Caveats and what changed since our earlier coverage
- Plans moved quickly. Alibaba Lite closed in March and April. Z.ai changed to credits on 2026-07-30. MiniMax replaced Token Plan with M Plan. By mid-November OpenCode had added Go Plus and Go Teams and raised its DeepSeek V4.1 Flash limit.
- Our earlier single-plan pieces predate several of these changes: OpenCode Go $10 plan review, GLM Coding Plan pricing, Xiaomi MiMo Token Plan guide, MiniMax Token Plan tiers and Ollama Pro vs Max. See also Ollama Cloud vs OpenRouter vs OpenCode Go and OpenCode Go slashes DeepSeek quotas.
- Requests are not comparable across vendors. A request on one plan is a dollar-capped slice of tokens, on another a counted call.
- We cite no benchmark numbers. None of these pricing pages publishes one we could tie to a plan.
- Recheck before buying. Vendors change prices without notice.
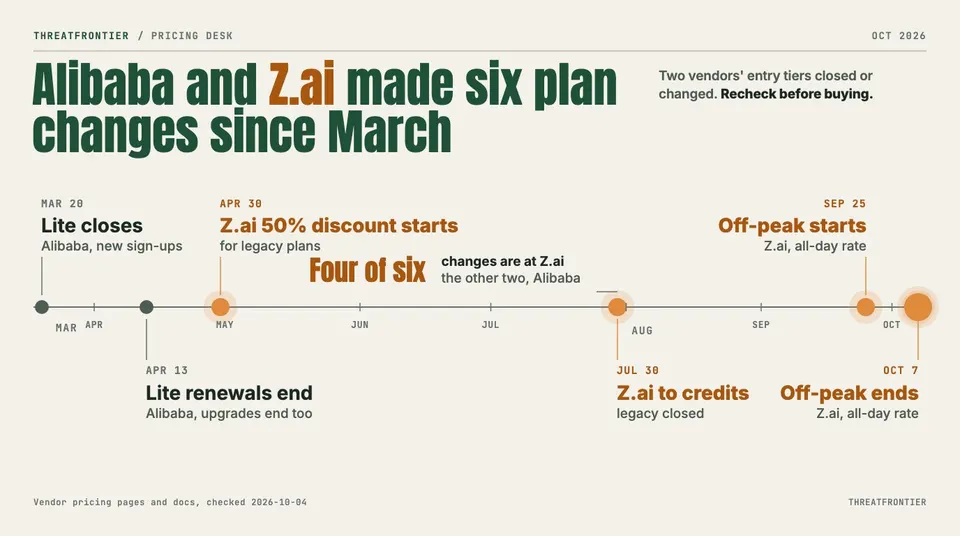
Six plan changes at Alibaba and Z.ai in 2026 (vendor docs, checked 2026-10-04).
Sources
- https://opencode.ai/docs/go/
- https://opencode.ai/go
- https://opencode.ai/docs/zen/
- https://chutes.ai/pricing
- https://commandcode.ai/pricing
- https://docs.z.ai/devpack/overview
- https://docs.z.ai/devpack/transition.md
- https://docs.z.ai/guides/overview/pricing.md
- https://docs.z.ai/legal-agreement/subscription-terms.md
- https://docs.z.ai/devpack/notice/usage-revision.md
- https://mimo.mi.com/docs/en-US/news/latest/token-plan-release
- https://www.alibabacloud.com/help/en/model-studio/coding-plan
- https://ollama.com/pricing
- https://www.kimi.ai/help/membership/membership-pricing
- https://platform.minimax.io/docs/guides/pricing-token-plan
- https://platform.minimax.io/docs/m-plan/token-plan-notice.md
- https://api-docs.deepseek.com/quick_start/pricing
- https://synthetic.new/pricing
- https://openrouter.ai/pricing
- https://www.cerebras.ai/pricing
- https://fireworks.ai/pricing
- https://threatfrontier.com/articles/qwen4-max-preview-token-plan-only-ends-nov-25