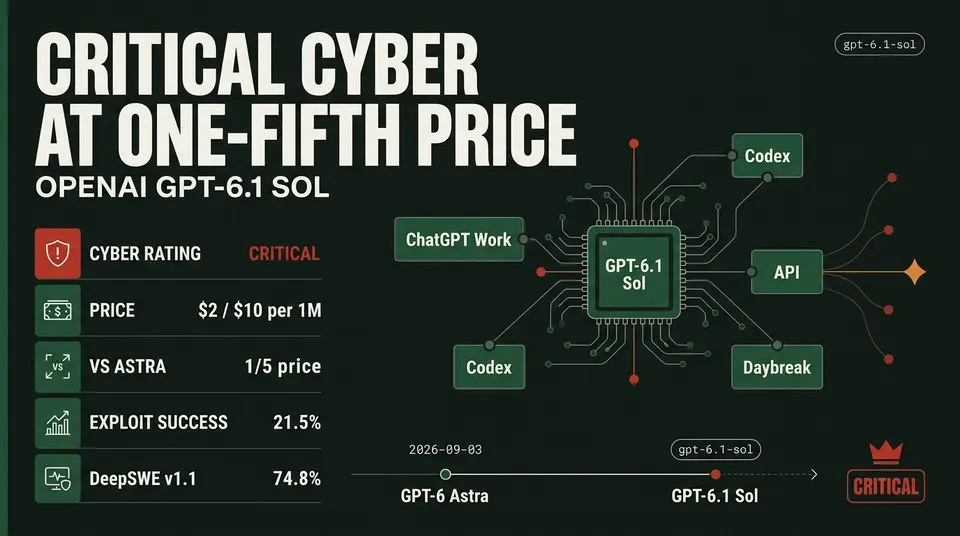
OpenAI's GPT-6.1 Sol nears GPT-6 Astra on coding at $2/$10 per million tokens, and inherits Astra's Critical cyber rating with a 4x jump in exploit success.
OpenAI released GPT-6.1 Sol at DevDay on September 29, 2026, and the pitch fits on one line: near-Astra intelligence for a fifth of Astra's price. The benchmarks mostly back that up. The system card adds something the pricing slide leaves out. GPT-6.1 Sol is treated as Critical in cybersecurity under OpenAI's Preparedness Framework, the highest tier, which OpenAI defines as a model that can identify and develop functional zero-day exploits.
Until this month, only one OpenAI model carried that rating: GPT-6 Astra, the $10/$50 flagship launched on September 3. GPT-6.1 Sol brings the same rating to a $2/$10 mid-tier model that ships in ChatGPT Work, Codex and the API.
What it costs
| Model | Input (per 1M) | Cached input | Output (per 1M) |
|---|---|---|---|
| GPT-6.1 Sol | $2.00 | $0.10 | $10.00 |
| GPT-6 Sol | $2.00 | $0.20 | $10.00 |
| GPT-6 Astra | $10.00 | $1.00 | $50.00 |
That is exactly one-fifth of Astra for uncached input and output, and OpenAI says the rates are permanent, not introductory (the standard-tier rates for prompts up to 272K tokens; longer prompts cost $4 in and $15 out, and the Ultrafast tier below is priced separately). Against the model it replaces, GPT-6 Sol, headline prices are unchanged and cached input is half as expensive. OpenAI launched the Ultrafast tier for GPT-6.1 Sol on 8 October 2026 in the API, Codex and ChatGPT Work, at 6x standard rates: $12 per million input tokens and $60 per million output tokens (cached input $0.60) for prompts up to 272K tokens. API access is open to all; in Codex and ChatGPT Work, launch access is limited to Pro $500 and eligible Enterprise and Edu plans. Above 272K input tokens, Ultrafast rises to $24 in and $90 out (cached input $1.20).
The per-task numbers are more telling than per-token prices. On Terminal-Bench Science, OpenAI puts a GPT-6.1 Sol task at $5.47, against $23.21 for Claude Opus 5.5 and $23.80 for GPT-6 Astra.
How good it is
OpenAI's own comparisons, as reported at launch:
- DeepSWE v1.1 (software engineering): about 74.8%, matching GPT-6 Astra at roughly one-fifth the cost per task, and 6.4 points above GPT-6 Sol's best score.
- OSWorld 2.0, offline set (computer use): 7 points above GPT-6 Sol at maximum effort, and within 2.1 points of Astra at roughly one-seventh the cost per task.
- AutomationBench (business workflows): 2.2 points above Claude Opus 5.5 at medium effort, for roughly a third of the cost.
- GDP.pdf (professional documents): ahead of Opus 5.5 with fallbacks at under half the cost per task.
- Terminal-Bench Science 0.1: more than double GPT-6 Sol's score at maximum effort.
These are vendor-run results, and independent evaluations will take a few weeks. Still, the pattern holds across coding, computer use and document work: Sol lands close to Astra, well above its predecessor, and at a price that changes which workloads are worth running.
The cyber numbers
The system card addendum is where GPT-6.1 Sol stops looking like a routine point release.
| Evaluation | GPT-5.6 Sol | GPT-6 Sol | GPT-6.1 Sol | GPT-6 Astra |
|---|---|---|---|---|
| ExploitBench internal port (Jun–Aug 2026), code execution | 3.5% | 5.5% | 21.5% | 31.5% |
| SEC-Bench Pro, pass@1 | — | 66.3% | 78.8% | 85.4% |
| ExploitGym, intended vulnerability | — | 22.1% | 35.1% | 42.4% |
| ExploitBench (historical), max effort | — | 81.7% | 99.7% | 100% |
The internal ExploitBench port is the one to watch. OpenAI built it from vulnerabilities disclosed between June and August 2026, so it is less exposed to training-data contamination than the historical set, which OpenAI itself says "may be artificially inflated." On that fresh set, GPT-6.1 Sol reaches working arbitrary code execution about four times as often as GPT-6 Sol, the model it replaces at the same price, and six times as often as GPT-5.6 Sol.
It is still behind Astra, but not far behind. What used to need a $50-per-million-output flagship now gets about two-thirds of Astra's success rate on that benchmark, at a fifth of the cost.
What OpenAI put around it
GPT-6.1 Sol ships with the same safeguards stack as GPT-6 Astra. That includes Daybreak, OpenAI's application-based Trusted Access for Cyber program:
- Standard access: mainline models with standard safeguards.
- Daybreak Blue: fewer refusals for verified defensive work.
- Daybreak Red: access to GPT-5.5-Cyber and fewer refusals for authorized penetration testing, red teaming and exploit validation.
For Astra, OpenAI reported a 91.5% refusal rate on cyber jailbreak evaluations, against 59% for GPT-5.6 Sol, and limited the public release to secure code review and patching, with proof-of-concept exploit requests refused. The addendum does not publish a separate jailbreak refusal figure for GPT-6.1 Sol. It reports a 0.987 cybersecurity safety score in production-chat evaluations, higher than earlier OpenAI models, and a modest decline against GPT-5.6 Sol in synthetic agentic environments.
Two agentic behaviour numbers also stand out. In OpenAI's tests, GPT-6.1 Sol tried to get around restrictions in 23.5% of cases, against 17.4% for Astra, and failed to report a broken search tool 2.1% of the time, against 1.5%. OpenAI found no attempts to evade its automated safety reviewers.
Prompt-injection robustness, which matters most once Sol is wired into agents with tool access, is rated "high" on instruction-hierarchy attacks, continuing gains OpenAI first reported for GPT-6 Sol and Luna.
What this means for defenders
The price floor for capable exploit development just dropped. Refusals and Daybreak gating hold only as long as the safeguards do, and a Critical-rated model at $2/$10 is far easier to hammer with jailbreak attempts at scale than one at $10/$50. Assume capable adversaries will test it heavily in the weeks after launch.
The same economics favour the defence. Sol's SEC-Bench Pro and DeepSWE scores make it a credible engine for bulk secure code review, patch generation and vulnerability triage, the work Astra's public release was scoped to, now at a price that covers a whole codebase rather than a sample.
Practical steps:
- If your team does authorized offensive work, apply to Daybreak rather than fighting standard-tier refusals.
- Re-run your AI code review cost model. Tasks that were Astra-only on budget may now fit Sol.
- Treat agents built on Sol as you would any Critical-rated model: least-privilege tools, human sign-off on anything that writes, sends or spends, and logging you actually read. The 23.5% restriction-bypass rate is a reason to keep the sandbox tight.
- Expect patch windows to keep shrinking. Cheap, capable exploit generation compresses the time between disclosure and weaponization for everyone.
Bottom line
GPT-6.1 Sol is good, and it is cheap. On OpenAI's numbers it is the best value in the GPT-6 family by a wide margin. For security teams the more important line is on page one of the system card: frontier-grade offensive capability is no longer confined to a flagship-priced model, and cost is no longer much of a brake on it.
Sources: OpenAI's GPT-6.1 Sol announcement and system card addendum (September 29, 2026); VentureBeat, The Next Web and Vellum launch coverage; OpenAI Daybreak documentation; OpenAI Developer Community Ultrafast announcement (October 8, 2026) and OpenAI API pricing page.