TensorFold's fast OpenAI-compatible LLM server added optional API keys in v0.6.5; with none set, every route is open. Loopback limits risk; 0.0.0.0 exposes it.
Update (2026-10-12): This article was written against TensorFold v0.6.0, which had no authentication. API keys arrived in v0.6.5 (October 3) and the native Zig server in v1.0.0 (October 7) kept them; v1.0.7 is the latest (October 11). Authentication is optional and off by default: with no key set, every route is still open. See the update below. NVIDIA cards other than the GB10 stay on the Python 0.6.x line, whose docs still bind
0.0.0.0with no key.
TensorFold is the local inference engine people have been passing around this week. Early users report roughly 4x faster decoding on Apple Silicon with output identical to normal decoding, served through an OpenAI-compatible endpoint that any existing client can point at. The project shipped ten releases between September 27 and September 30, went to Apache-2.0 with version 0.6.0, and had 810 GitHub stars and 110 forks by October 2 (the repository showed about 1,160 stars and 200 forks on October 10).
We read the v0.6.0 source to see what a team inherits when a developer runs tensorfold serve on a work machine. The engineering is careful in several places. But at v0.6.0 the server had no authentication of any kind, and it is still open on any server where no key is set. That is a common design choice for local model servers, and the safety of the whole setup comes down to the listen address.
What TensorFold is
TensorFold serves language models on Apple Silicon through MLX, and on NVIDIA GPUs through CUDA. Its speed comes from exact speculative decoding: draft tokens run through parallel lanes, the model verifies them together, and only tokens that match serial decoding are kept. The supported models include Qwen3.8-27B, Nemotron 3.5 Lightning, GLM-5.3-Flash and Gemma 4.
Both backends expose the same HTTP surface:
| Endpoint | What it does |
|---|---|
POST /v1/chat/completions, POST /v1/completions | Runs a prompt on the loaded model |
POST /v1/responses | OpenAI Responses API, stored in memory by default |
GET / DELETE /v1/responses/{id} | Reads or deletes a stored response |
GET /v1/models | Lists the served model ids |
GET /health | Status, batch size and memory figures |
GET /metrics | Prometheus counters |
No credentials, by design (at v0.6.0)
In v0.6.0 none of those routes checked a credential. The CLI had no API-key flag, and the request handlers never read an Authorization header. Anyone who can reach the port can run prompts on the model, read the health and metrics data, and use the Responses API.
The default keeps that contained. --host defaults to 127.0.0.1 and the port to 8080, so a plain tensorfold serve on a laptop is reachable only from that machine.
The NVIDIA instructions take a different path. The README and the runbook both start the CUDA server inside NVIDIA's PyTorch container with --network host and pass --host 0.0.0.0. That binds the unauthenticated API to every interface on the host. On a GPU box with a public address, or a DGX Spark on a flat office network, the model is open to everyone who can route to it.
The two-GPU setup adds a second open port. The runbook says plainly that the rendezvous port (29551 by default) and the link between the ranks "are not authenticated: keep them on a private link, or firewall the port to the peer."
Why an open model port matters
This is not a theoretical risk. Ollama has the same design, an unauthenticated API meant for localhost, and its exposed instances are now measured by the hundred thousand:
- Cisco, September 2025: a Shodan study found 1,139 exposed Ollama servers. 214 of them were actively serving models and accepting prompts without authentication.
- SentinelLABS and Censys, January 2026: 175,000 unique Ollama hosts exposed across 130 countries. Nearly 48% supported tool calling. The researchers also traced a criminal service that scans for open instances, checks their quality and resells access.
That resale trade is LLMjacking: someone else's GPU produces spam, disinformation or anything else the buyer wants, and the owner pays for the power. TensorFold speaks the same OpenAI-style routes that the existing scanners already probe, so nothing new is needed to find it.
Localhost is not a wall
Binding to 127.0.0.1 stops other machines. It does not stop the browser on the same machine. We noted two things about how TensorFold's request handling meets the browser:
- It parses any body as JSON. The handlers read the body without checking
Content-Type. A web page can send a cross-origintext/plainPOST, which browsers allow without a preflight, and TensorFold will run it as a normal request. The page cannot read the reply, but it can make the model generate. How far this gets depends on the browser's local-network protections, which vary by browser and version. - It does not check the
Hostheader. That check is the usual defence against DNS rebinding, which turns a hostile page into a same-origin client of a localhost service. Here a successful rebind could read replies and stored responses.
We did not build working attacks for either, and modern browsers keep adding friction for public pages talking to private addresses. But "it only listens on localhost" is a weaker guarantee than it sounds for a service with no credentials.
What the code gets right
Several defaults in the source are more careful than they need to be:
- Image URLs are off. The vision models accept data URLs. Fetching a remote image needs
--vision-urls, and even then onlyhttps://URLs are accepted. That shuts off the obvious server-side request forgery path. - Request bodies are capped at 32 MiB on both backends.
- Stored responses use random ids. The Responses store keeps up to 1,024 responses or 256 MiB in memory, and every id is a random UUID, so an attacker cannot list or guess other users' conversations.
- Weights load as safetensors from Hugging Face, not as pickle files that run code when loaded.
- Updates are pinned to release tags.
tensorfold updateinstalls the newest tagged release rather than whatever is on the main branch. The daily release check can be turned off withTENSORFOLD_NO_UPDATE_CHECK=1.
One thing to know about: setting TENSORFOLD_REQUEST_LOG appends every request body to a file in plain text, with only images redacted. It is useful for replaying traffic and easy to forget about once the debugging is done.
At publication the repository had no SECURITY.md and no published way to report a vulnerability (see the update below). For a project releasing several times a day, that is the gap most worth closing.
Update: API keys since v0.6.5
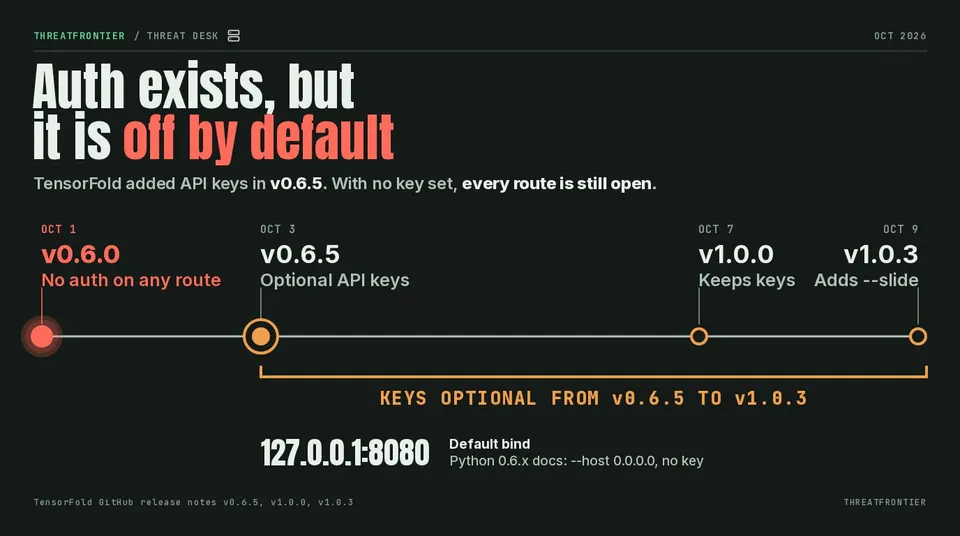
Timeline. v0.6.0 had no authentication. v0.6.5 (October 3) added API keys on both servers. v1.0.0 (October 7) is the native Zig engine and HTTP server for Apple silicon and the GB10; the release notes say NVIDIA GPUs other than the GB10 "stay on the Python line", which is 0.6.6. 1.0.1 and 1.0.2 shipped on October 7, 1.0.3 on October 9 and 1.0.4 on October 10. 1.0.5, 1.0.6 and 1.0.7 followed on October 10 and 11; their release notes change no authentication behaviour apart from a fix in 1.0.5 so that a request keeps its key's label when the key file is reloaded, and we have not re-read their source. 1.0.4 changed only --slide.
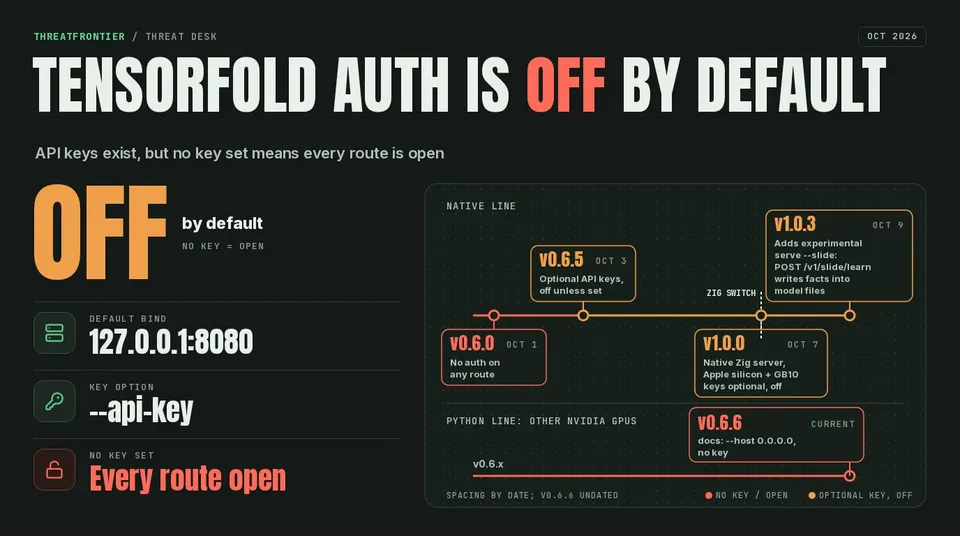
How keys work. The v0.6.5 release notes add:
- A key from
--api-key(repeatable),--api-key-file(one key, or alabel: keyline per key, reread onSIGHUP) or theTENSORFOLD_API_KEYenvironment variable. - Clients send
Authorization: Bearer <key>orx-api-key: <key>. /healthstays open./metricsneeds a key unless the server is started with--metrics-open.
What we read in the v1.0.3 source (1.0.4 changed only --slide, and we did not re-read 1.0.5 to 1.0.7; we read the source and did not run it):
- With no key configured, the authentication check returns true, so every route is open, as in v0.6.0. Keys are optional.
- The default bind is
127.0.0.1:8080, set in the command-line parser. If the host is not loopback and no key is set, the server logs "warning: non-loopback server has no API key; requests are open". - With a key set, every
/v1/*route is gated, along with/dashboard,/stats,/memory,/tokenizeand/models. Only/health(and/metricswith--metrics-open) stay open, andOPTIONSrequests pass. - The server refuses a key file that group or others can read and tells you to
chmod 600it. - The v1.0.3 RUNBOOK says: "To accept remote clients, choose
--host 0.0.0.0and configure--api-key-file", and that the default loopback server accepts local clients without a key. The--network hoststeps are gone from it.
What is still exposed.
- The Python 0.6.x line. NVIDIA GPUs other than the GB10 are still on 0.6.6. Its README and RUNBOOK still start the CUDA container with
--network hostand--host 0.0.0.0and no key, so that path is as exposed as the one this article described unless you add a key. - Any server with no key, on any version. Authentication does not switch itself on.
serve --slide, new in 1.0.3 and experimental, lets a Nemotron 3.5 Lightning server learn facts throughPOST /v1/slide/learn. Each fact is written into the checkpoint's safetensors shards, and the 1.0.3 release notes say "nothing undoes a learned fact". On a server with no key, anyone who can reach the port can permanently change the model files. Per the source, a key gates that route. 1.0.4 now refuses a model folder whose files are links to shared data, such as atensorfold pullfolder linked into the Hugging Face cache, where 1.0.3 learning would have rewritten the cached original; it asks for a copy made withcp -cRL.
Browser caveats. Our read of the 1.0.3 source found no check of the request Host or Content-Type header (only response headers turn up), so we expect the browser caveats above to hold when no key is set; we did not test this. A key closes both paths: a cross-origin page cannot send an Authorization or x-api-key header without a CORS preflight, so the plain text/plain POST trick no longer reaches a gated route. We did not test the preflight response.
As of October 10 we found no SECURITY.md at the repository's default path.
What defenders should do
- Set an API key and keep the loopback bind. On v0.6.5 or later, start TensorFold with a key from
--api-key-fileorTENSORFOLD_API_KEY, and leave it on127.0.0.1. Keep the key file owner-only (chmod 600) or the server will not start. Reach it from other machines through an SSH tunnel or a reverse proxy that requires authentication. On v0.6.0 to v0.6.4 there is no key support: upgrade, or keep a proxy in front. Other NVIDIA cards stay on the 0.6.x line, where 0.6.5 or later is the minimum and 0.6.6 is current. - Rewrite the 0.6.x CUDA instructions before you use them. Their README and RUNBOOK use
--network hostand--host 0.0.0.0with no key. Add a key and a firewall or proxy, and do not run--network hoston a machine with a public interface. On the native v1.0.x server, a remote bind should always come with--api-key-file. - Firewall port 29551 to the peer rank on two-GPU setups, or keep the ranks on a private link.
- Look for it on your network. Search for listeners on 8080 that answer
GET /v1/modelswith"owned_by": "tensorfold". That response is a reliable fingerprint. - Leave
--vision-urlsoff unless you need it, and unsetTENSORFOLD_REQUEST_LOGwhen you are done with it. - Pin a version. At this release pace, install a specific tag and review the changelog before upgrading a shared server.
TensorFold is a good piece of engineering, its laptop defaults are sensible, and it now has the key support it lacked at launch. Compare it with other local servers: the llama.cpp server flaw is a reminder that a model port needs patching as well as a key, and our guide to open-weight models for a 24GB Mac covers what people run on these machines. The risk comes from the copy-paste path to a GPU server, which is the same one that put 175,000 Ollama hosts online.