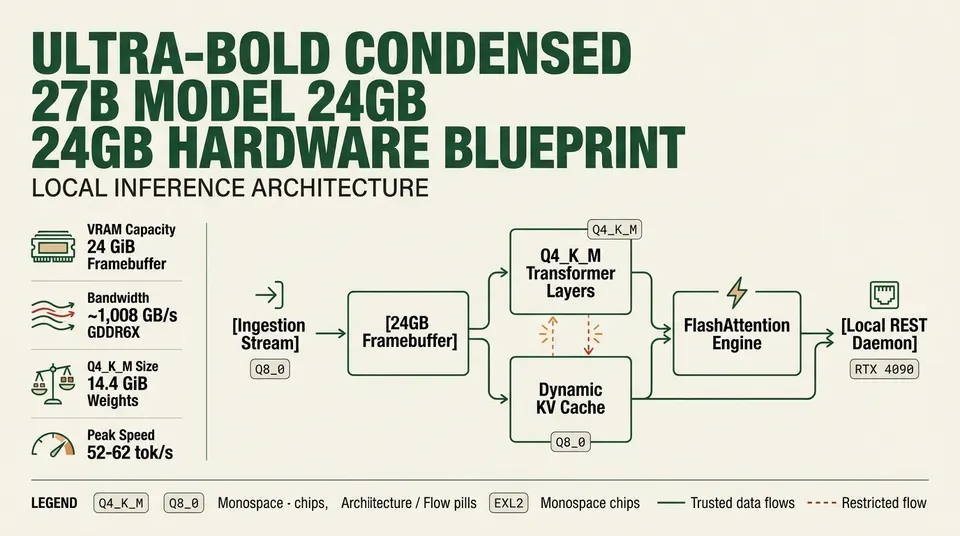
Local Deployment of 27B Large Language Models: The 24GB Hardware Blueprint
Learn how to run 27B LLMs on a 24GB GPU. Master VRAM sizing, GGUF/EXL2 quantization, and Ollama configs to achieve high-throughput local inference today.
· 7 minTopic
Coverage tagged 27b llm local deployment.
Learn how to run 27B LLMs on a 24GB GPU. Master VRAM sizing, GGUF/EXL2 quantization, and Ollama configs to achieve high-throughput local inference today.
· 7 min