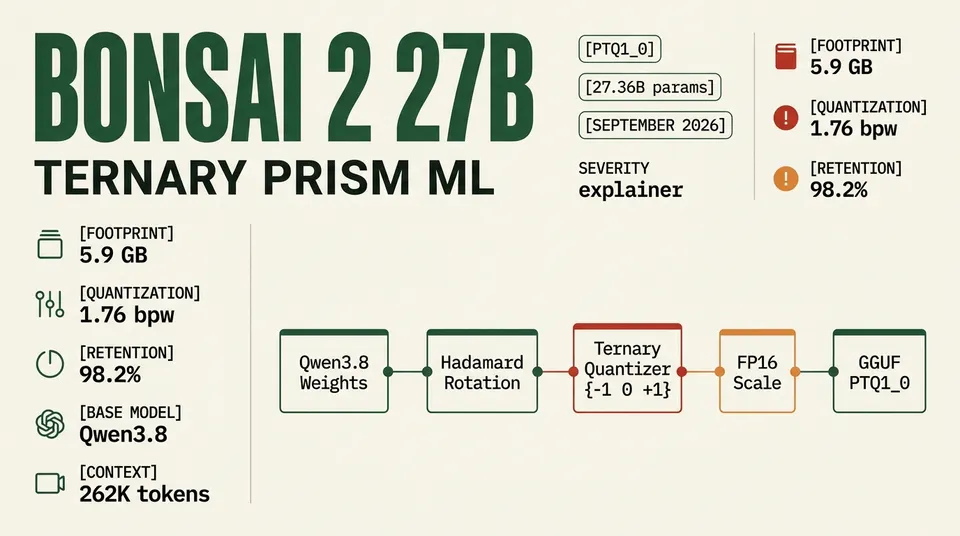
Ternary Bonsai 2 27B: Architecture, Benchmark Reality, and Runtime Limits
Prism ML’s Ternary Bonsai 2 27B compresses Qwen3.8 into 5.9GB at 1.76 bits per weight. Here is how the math works and what independent testing reveals.
· 10 minTopic
Coverage tagged qwen 3 8 27b.
Prism ML’s Ternary Bonsai 2 27B compresses Qwen3.8 into 5.9GB at 1.76 bits per weight. Here is how the math works and what independent testing reveals.
· 10 min
Compare Qwen 3.8 27B's 262K context window to vector RAG. Analyze KV cache VRAM limits, multi-hop reasoning decay, and hybrid enterprise AI architectures.
· 6 min
Explore Qwen 3.8 27B multimodal benchmarks, architecture, and deployment strategies. Learn how open-weights vision AI rivals proprietary enterprise APIs.
· 7 min